Audio Demonstrations
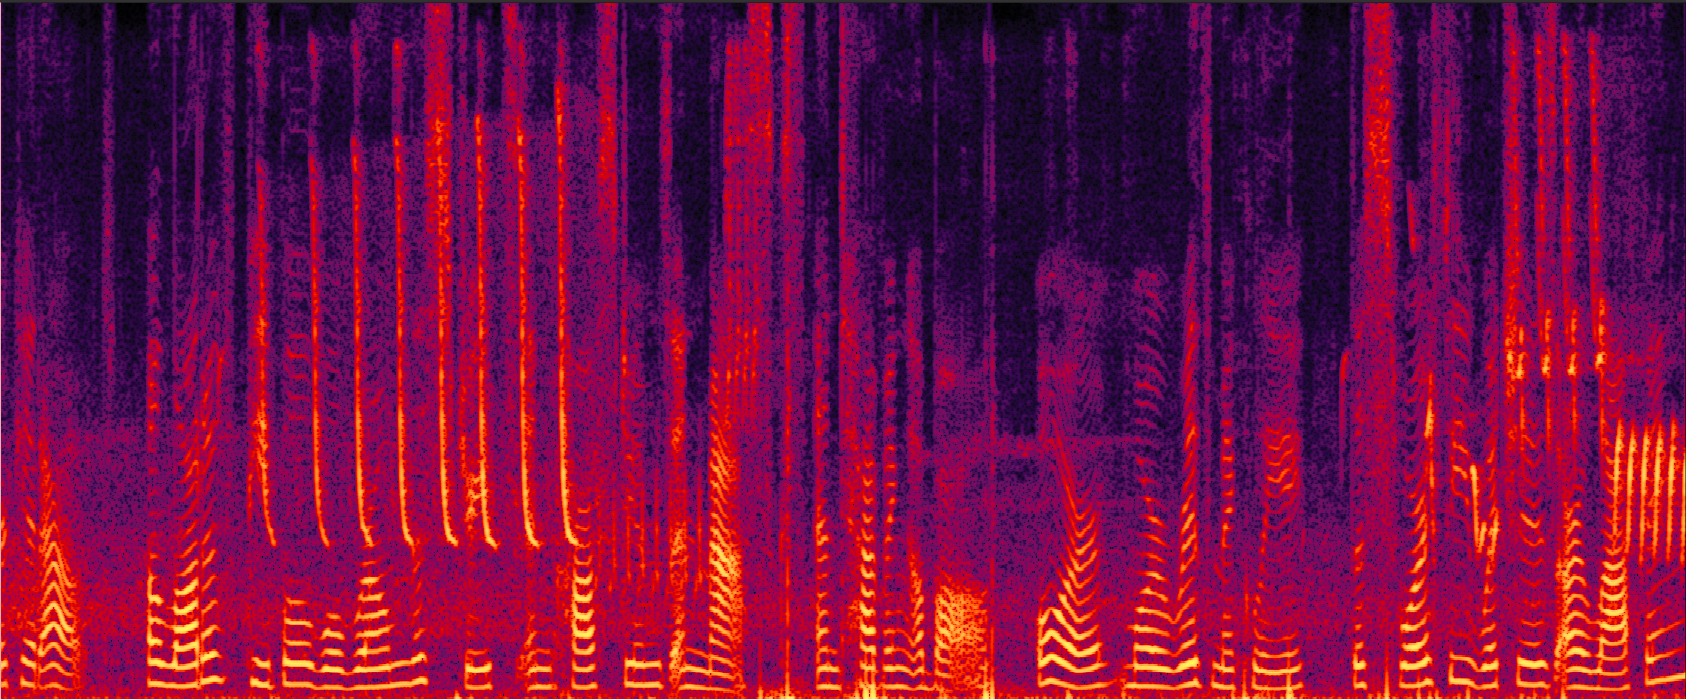
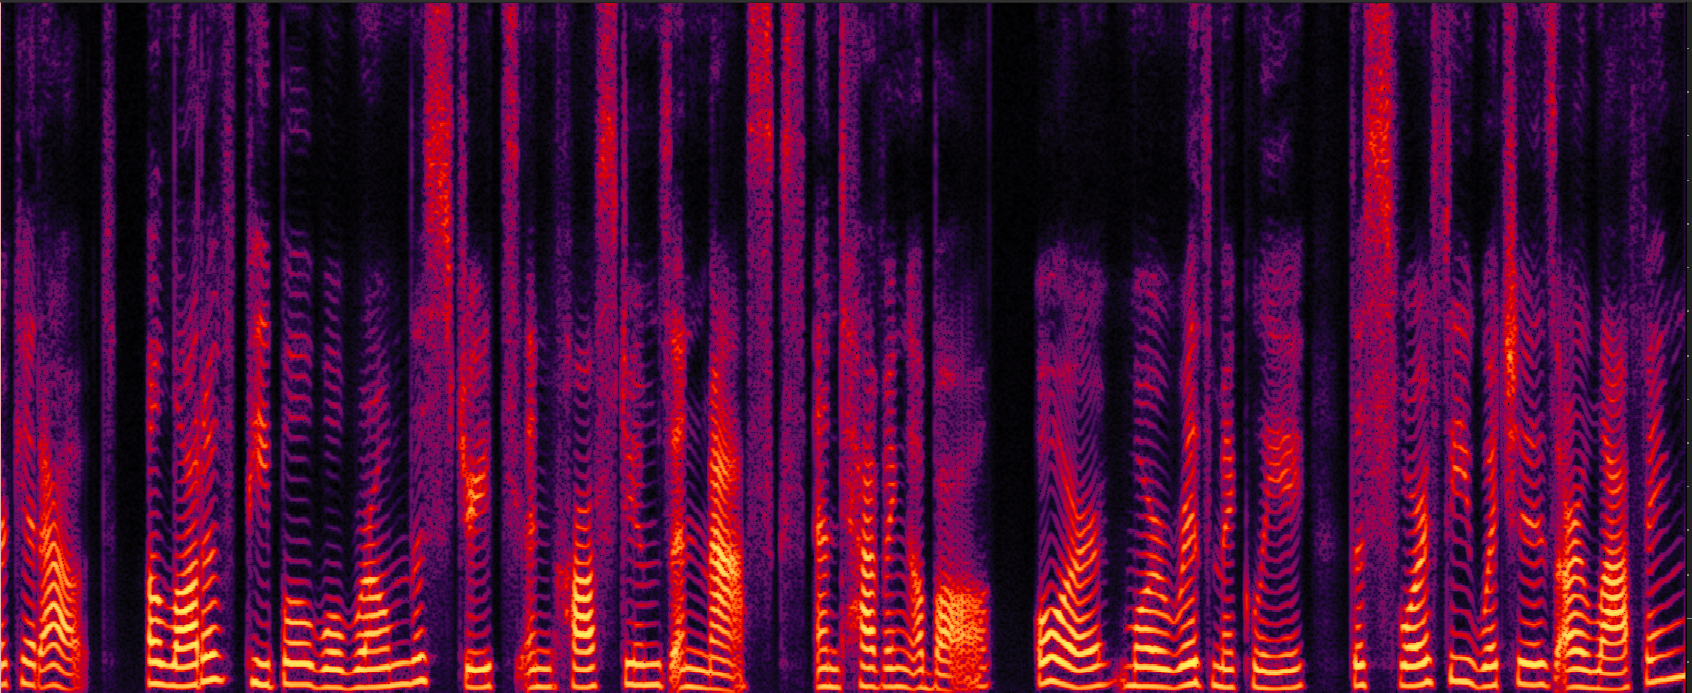
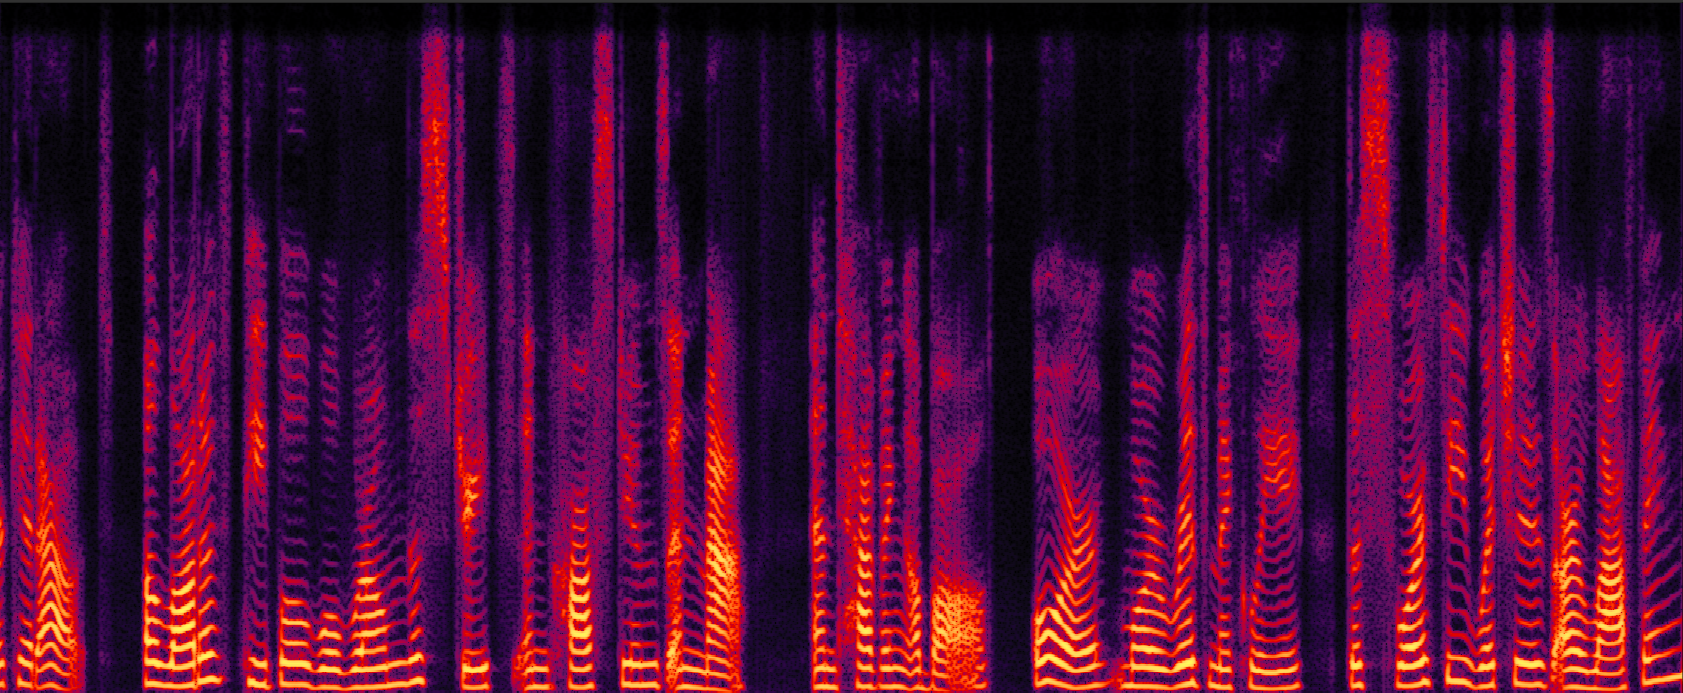
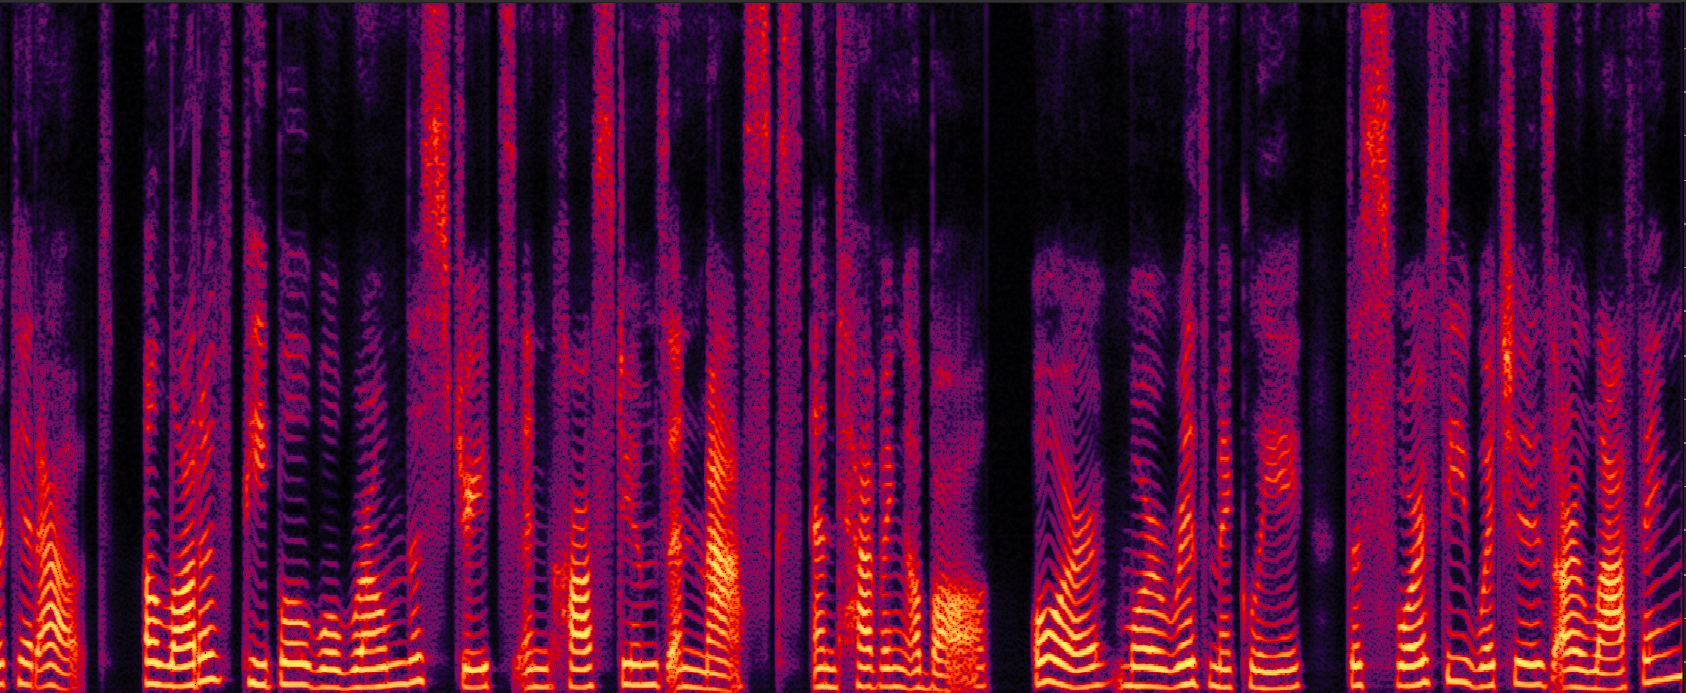
We present audio samples comparing DualSpecSE with baseline methods (SpatialNet and PGUSE) on three DNS Challenge test sets.
DNS Challenge: No-Reverb Test Set
Sample 1
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
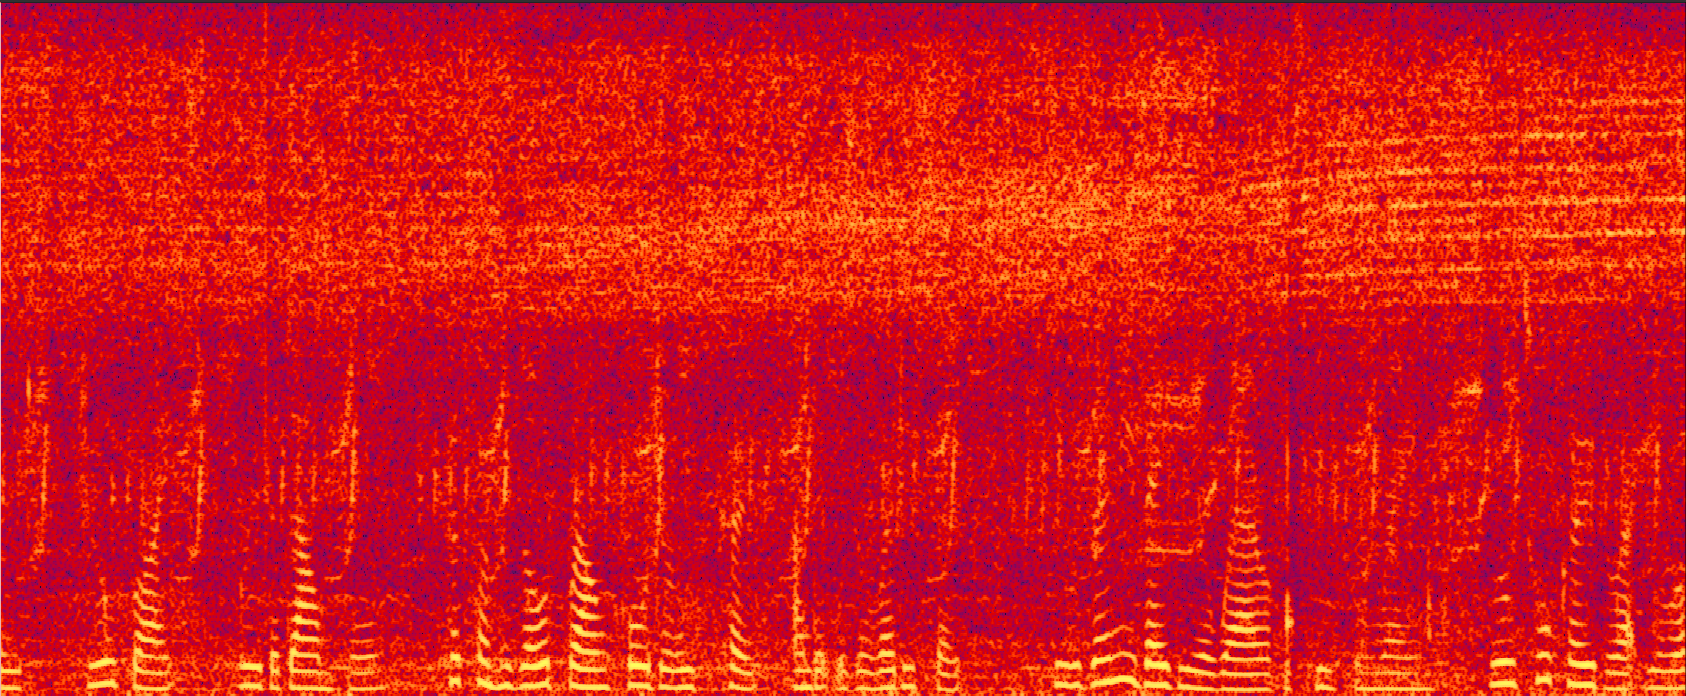
|
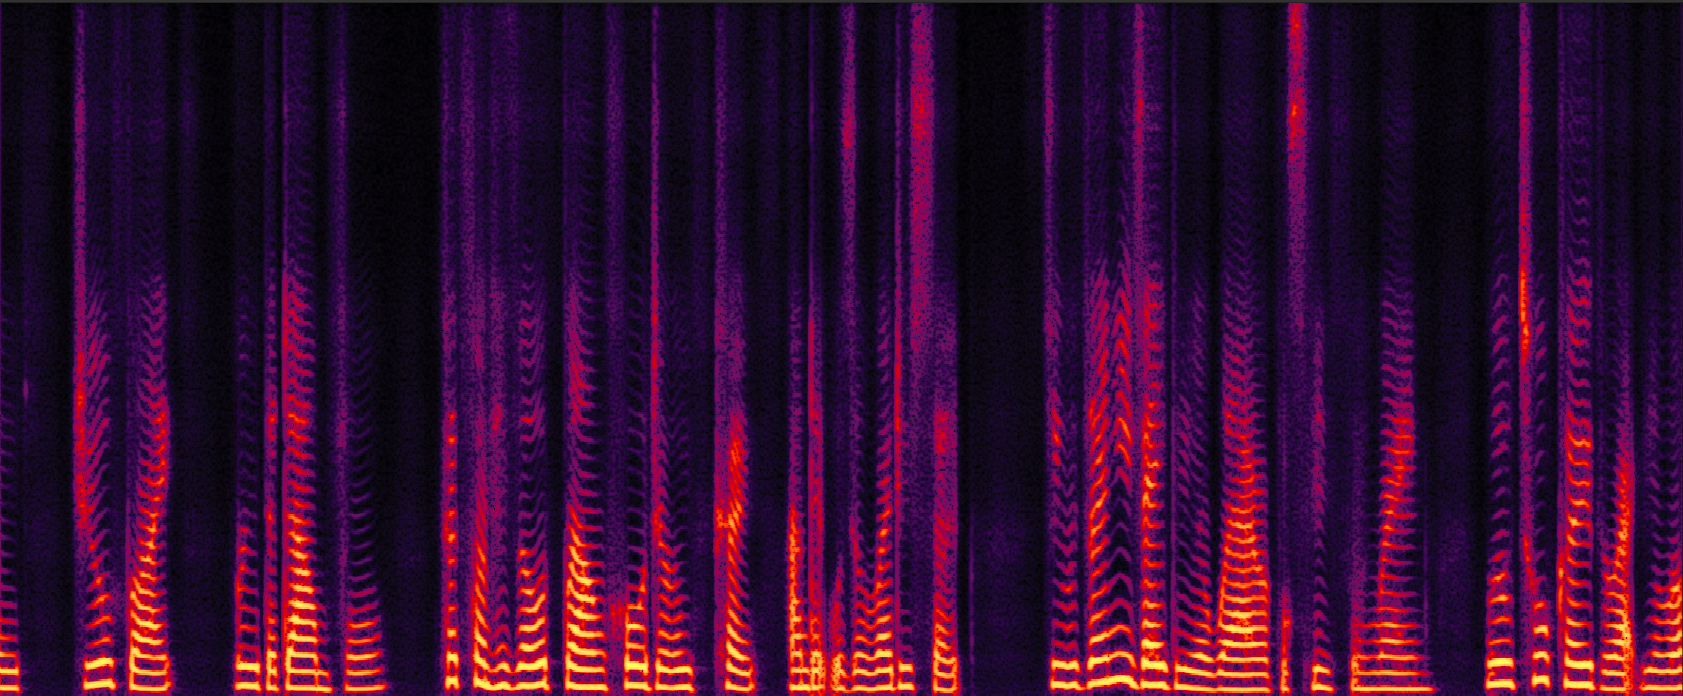
|
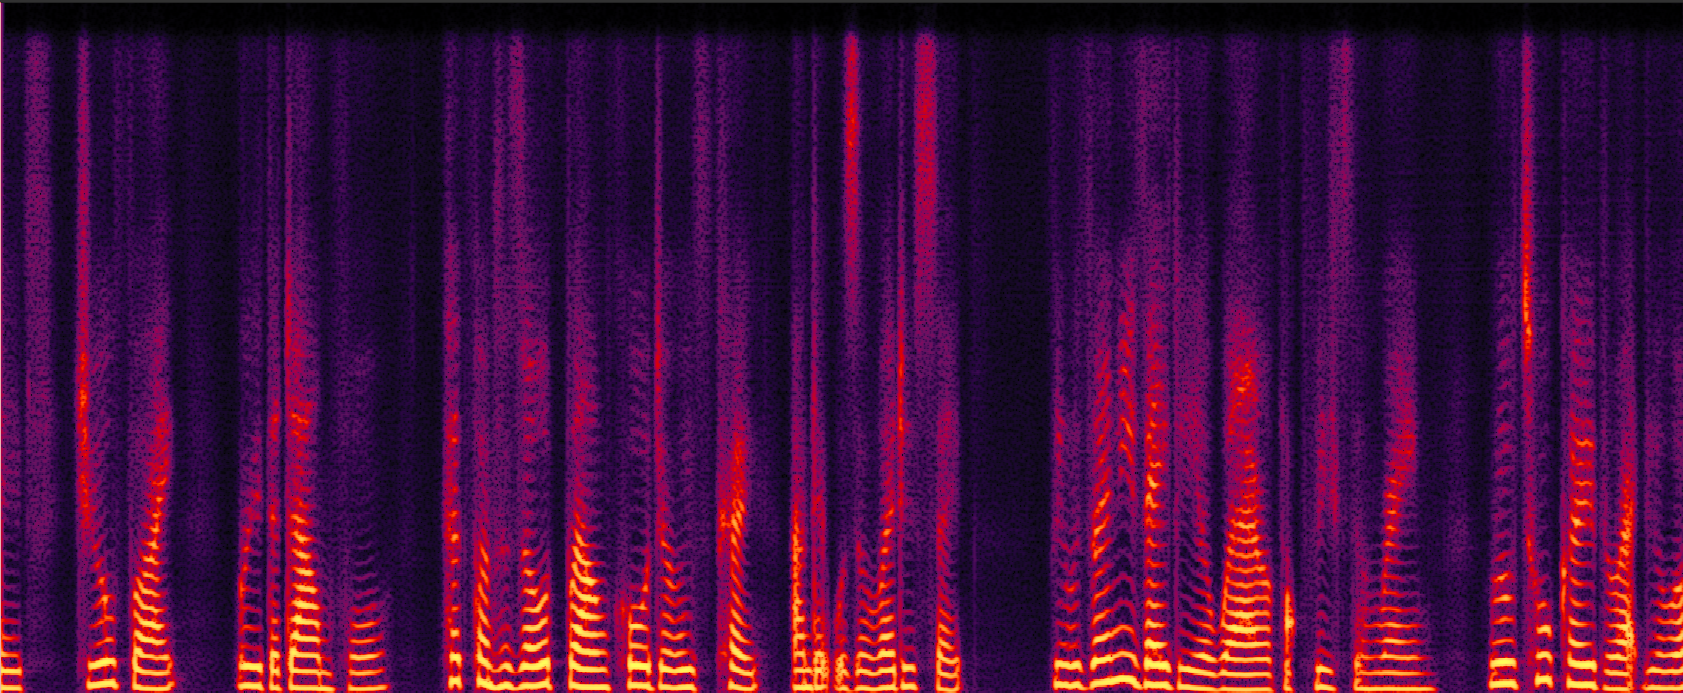
|
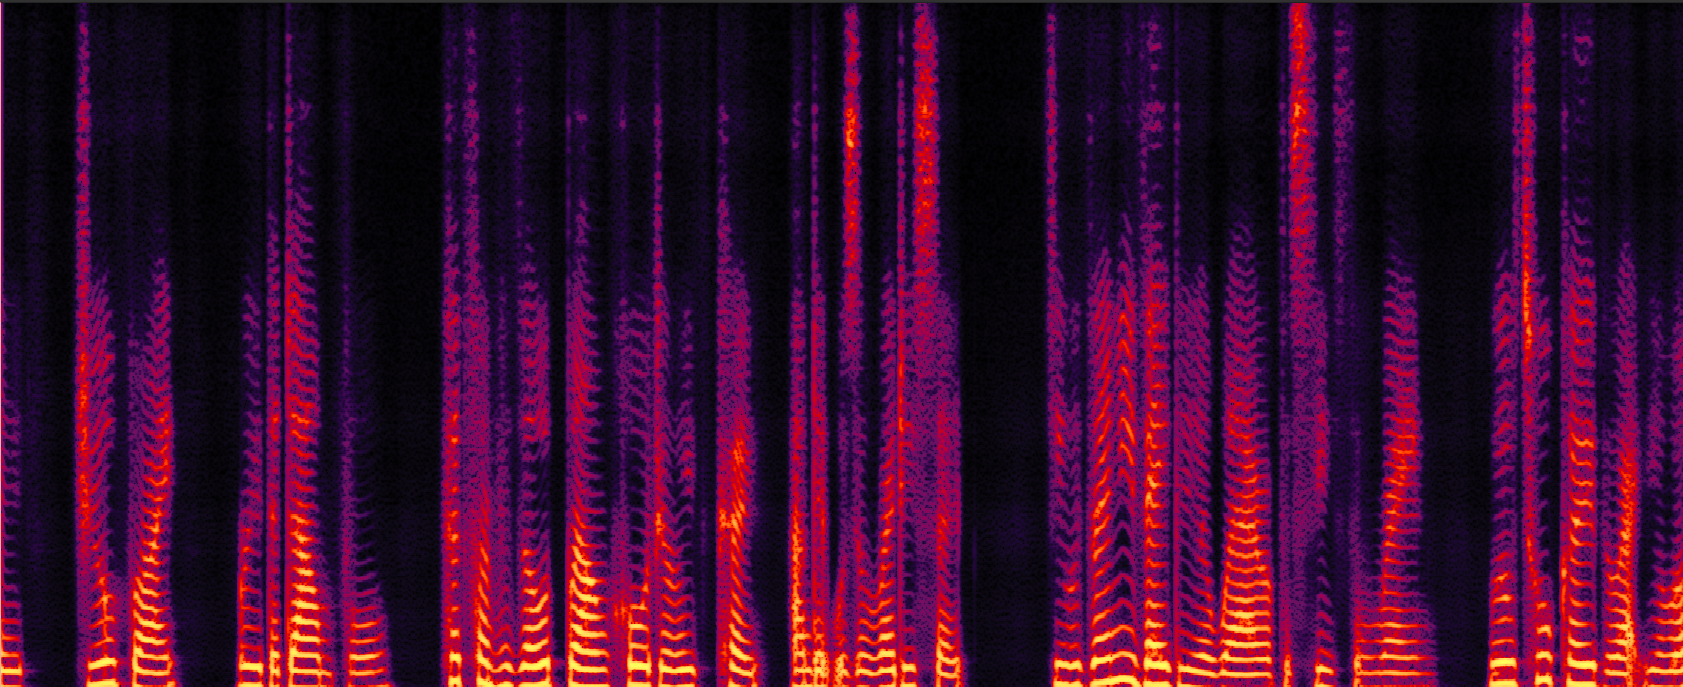
|
sample 2
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
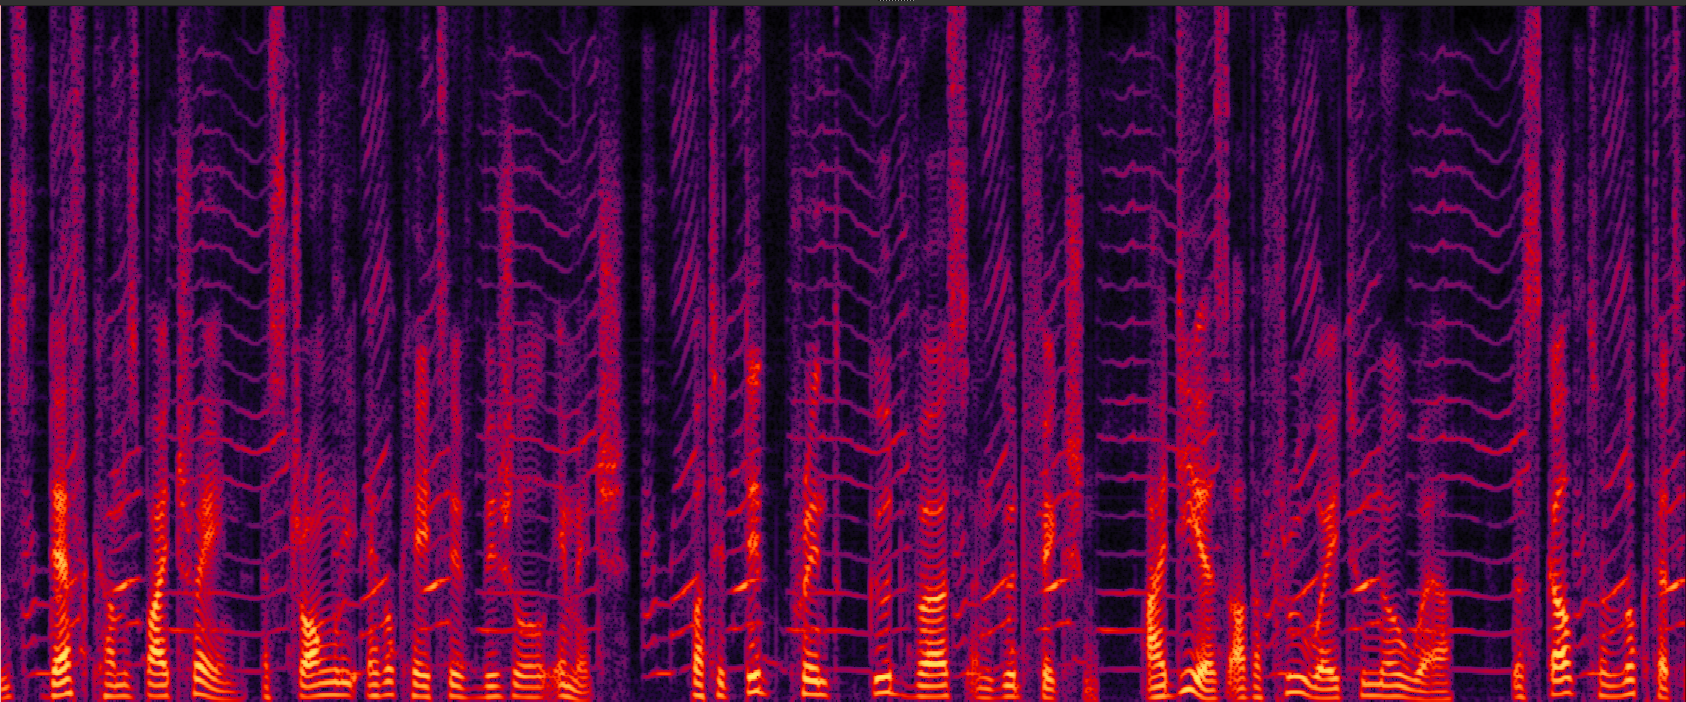
|
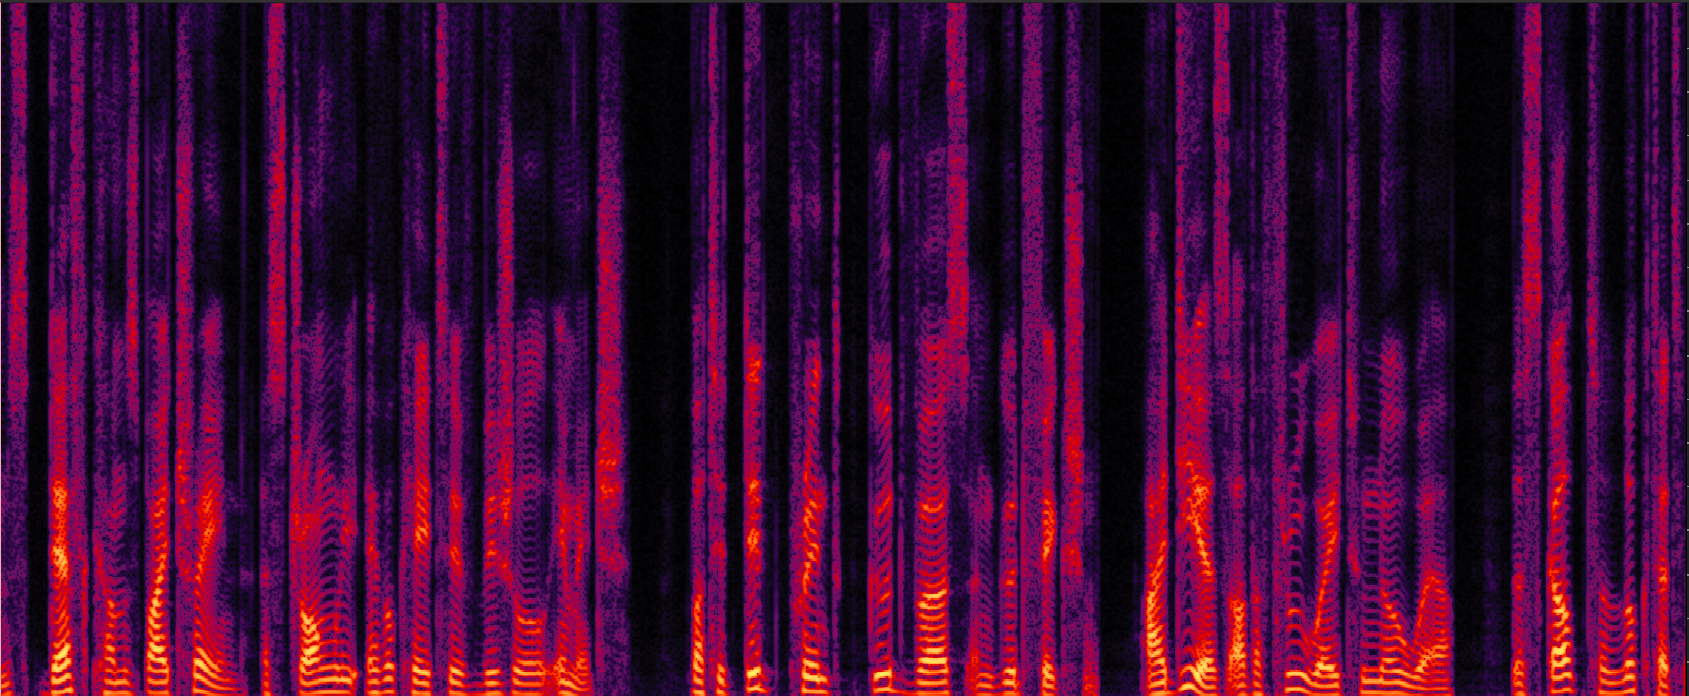
|
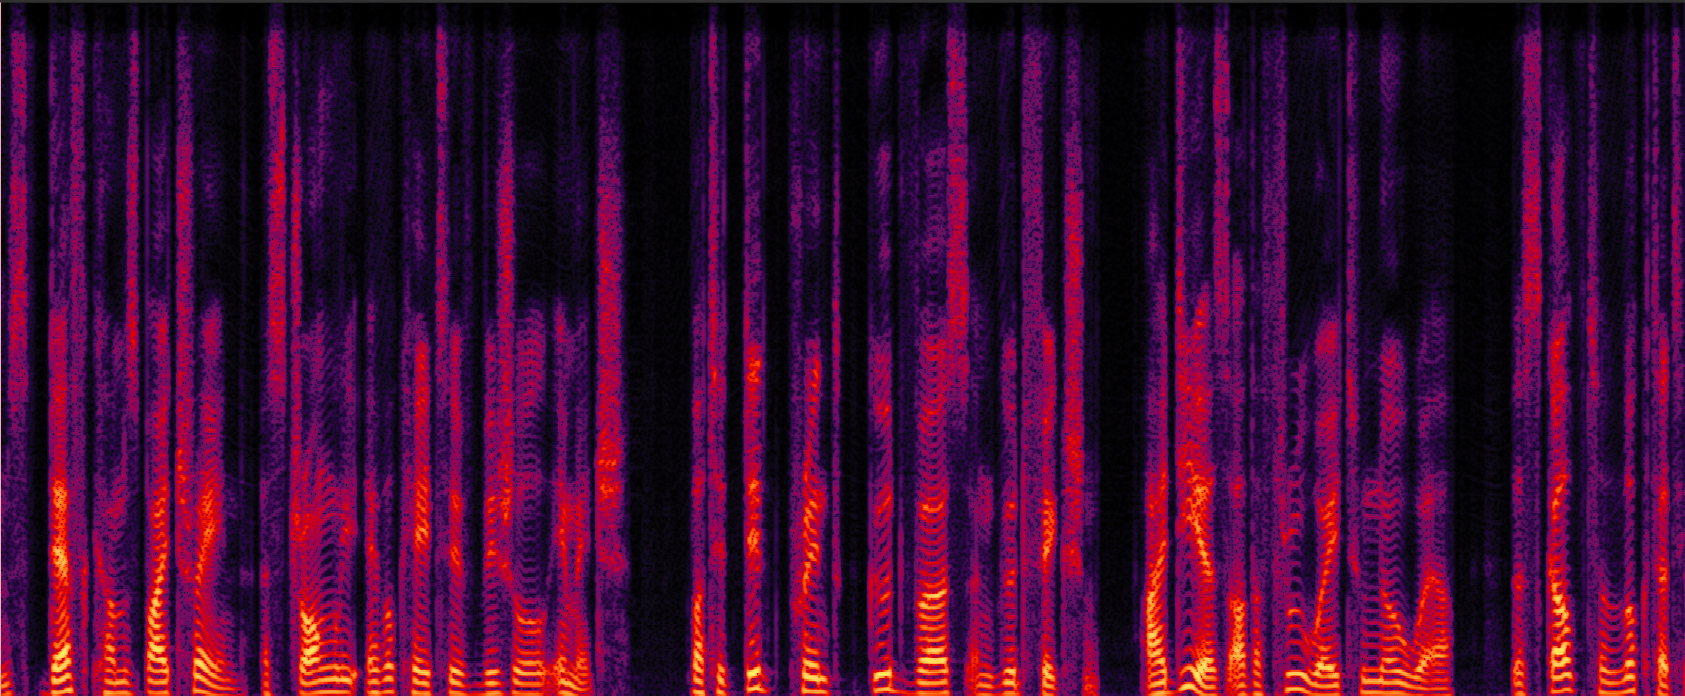
|
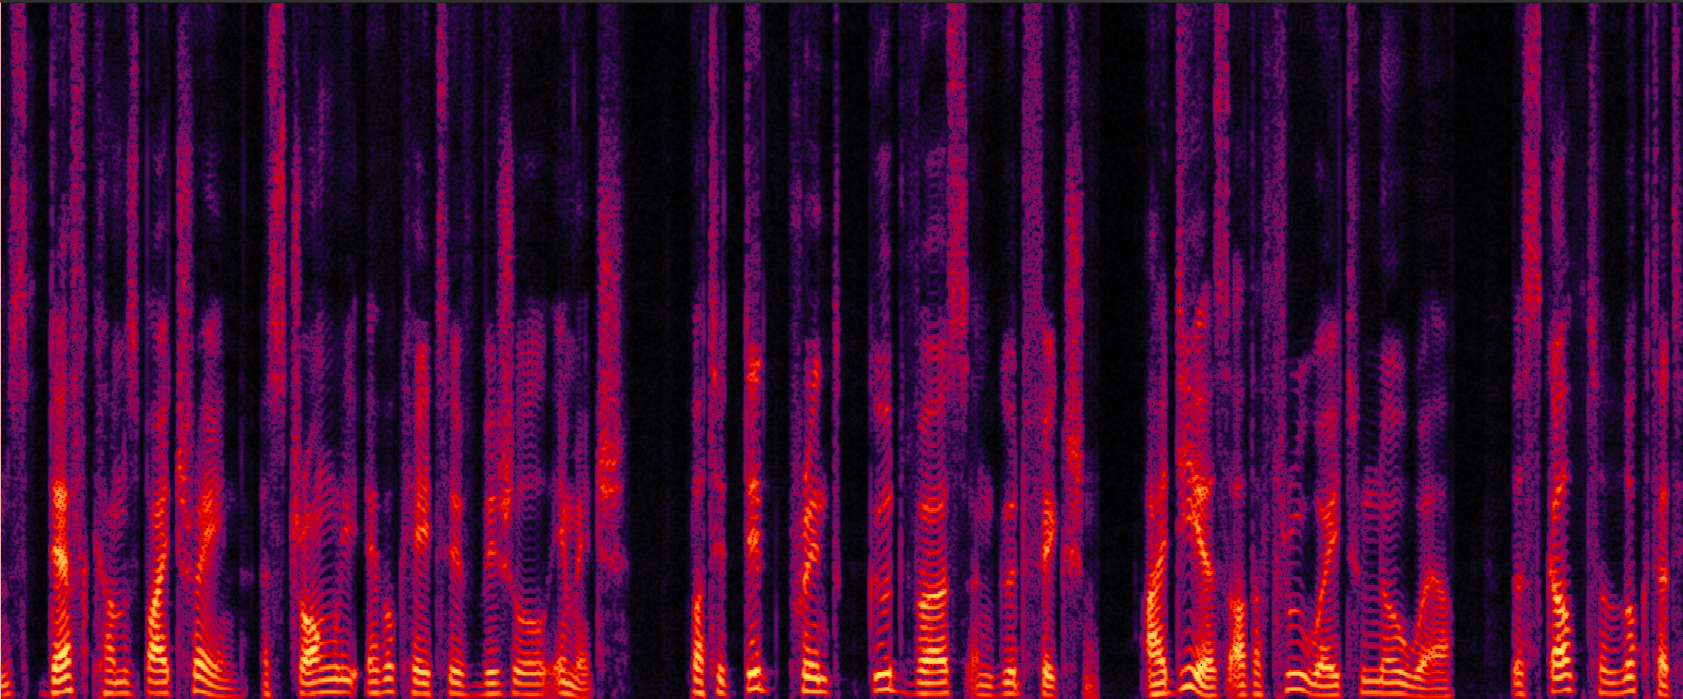
|
sample 3
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
|
|
|
|
DNS Challenge: With-Reverb Test Set
Sample 1
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
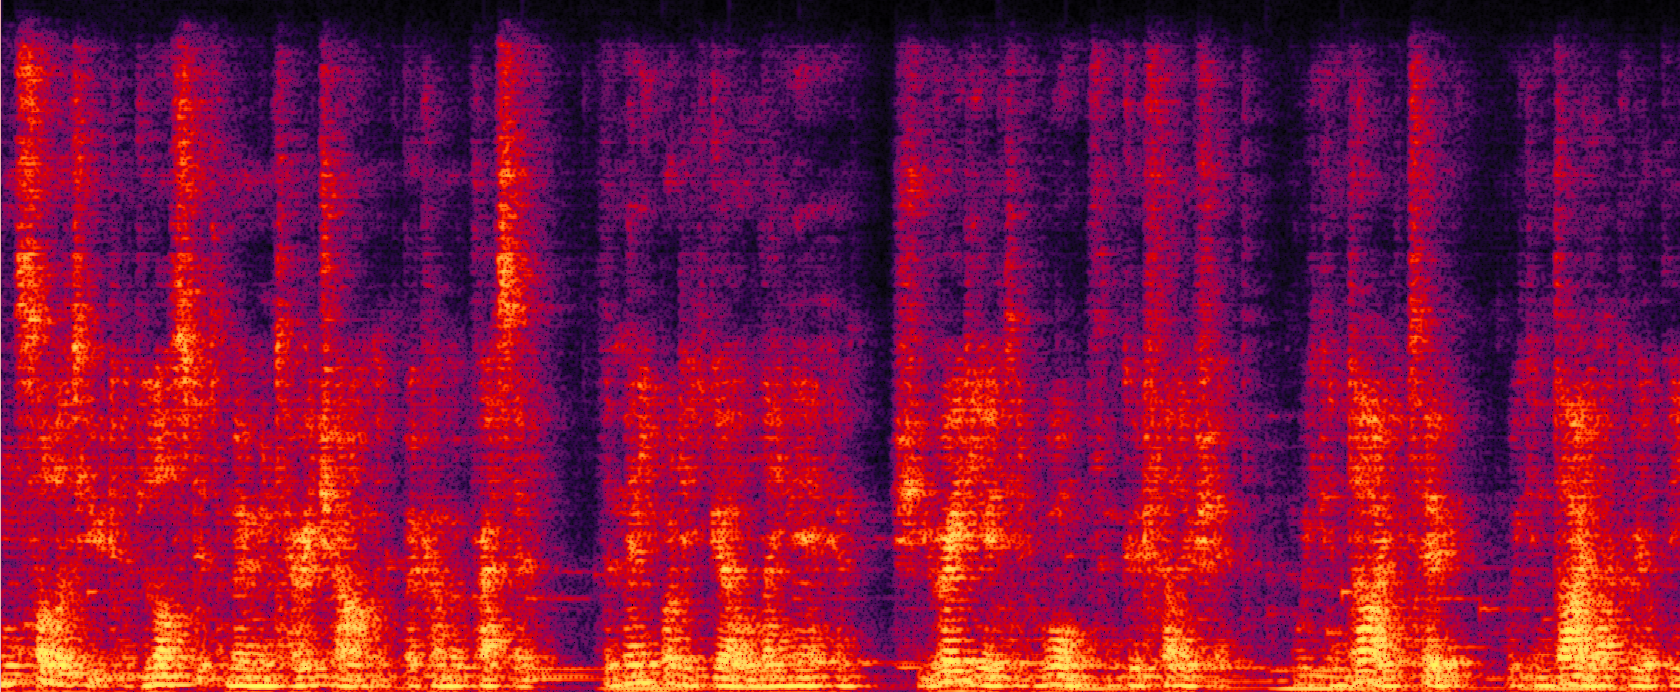
|
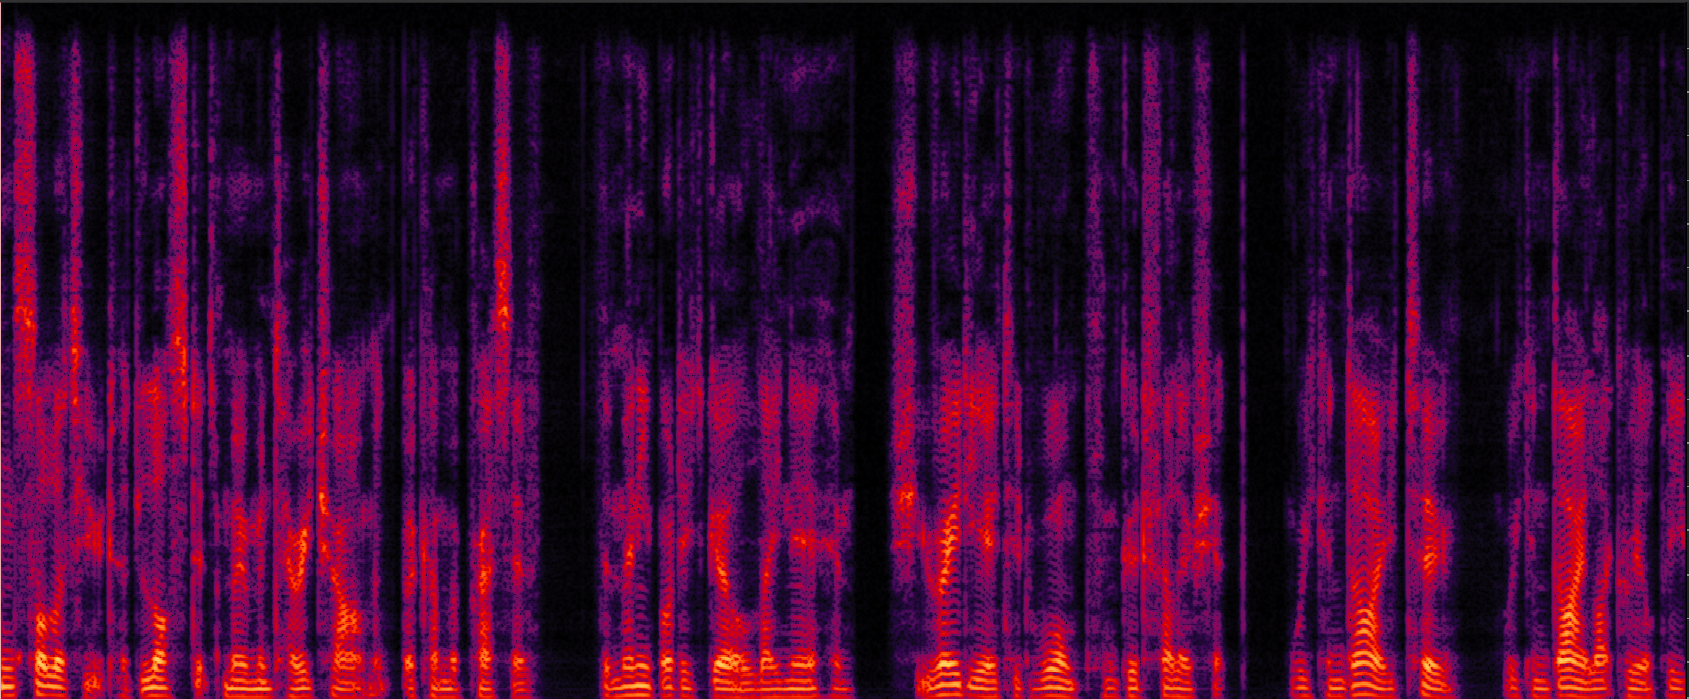
|
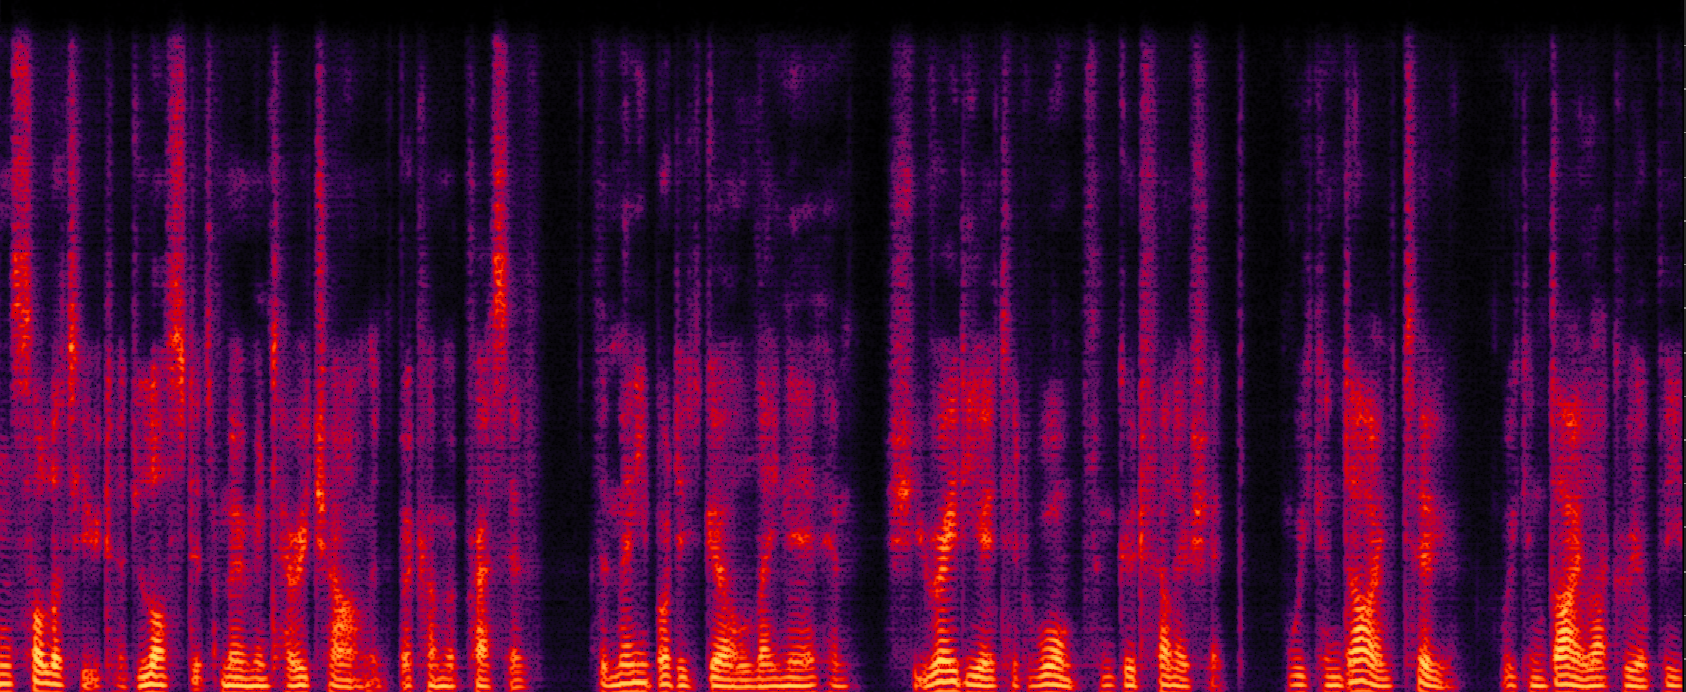
|
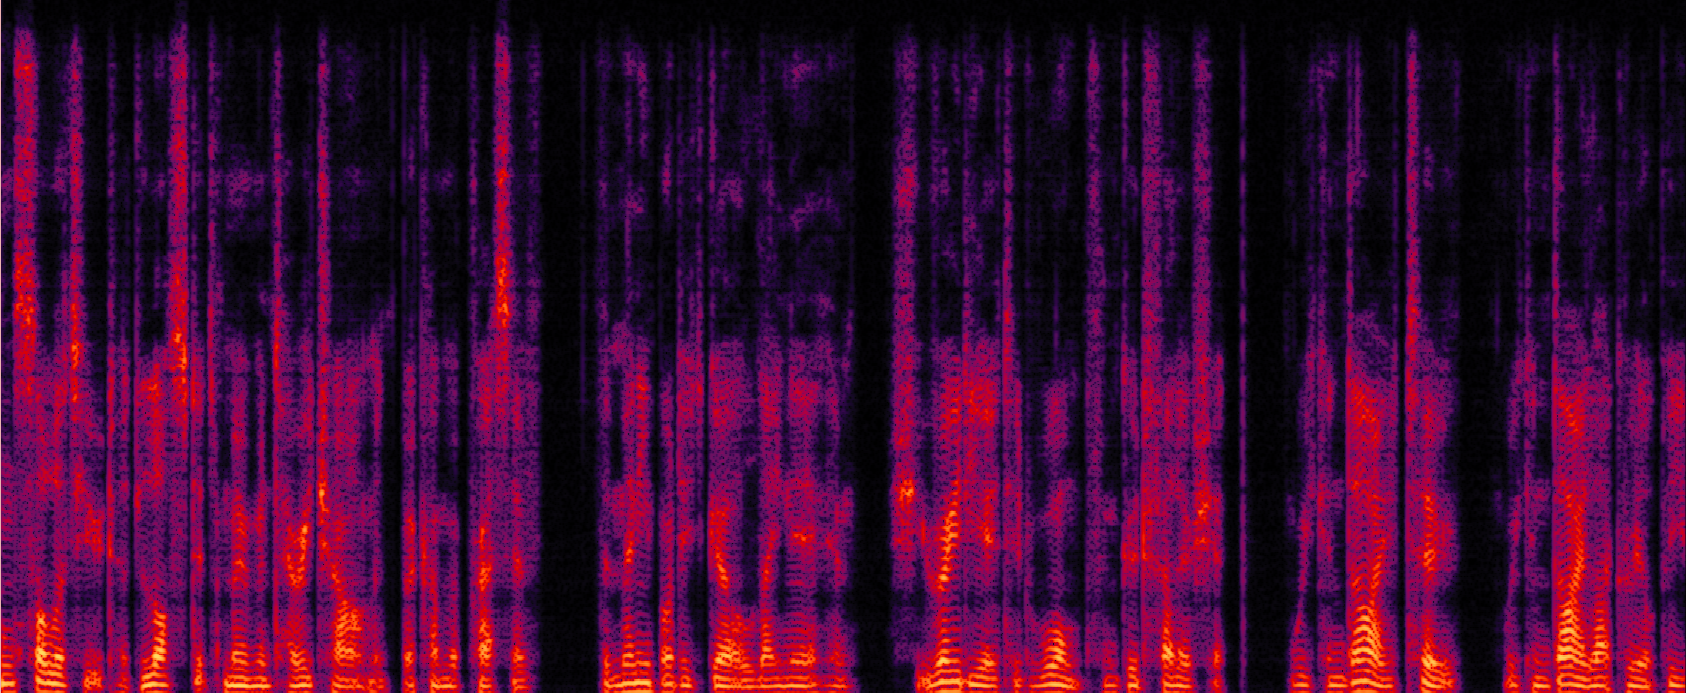
|
Sample 2
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
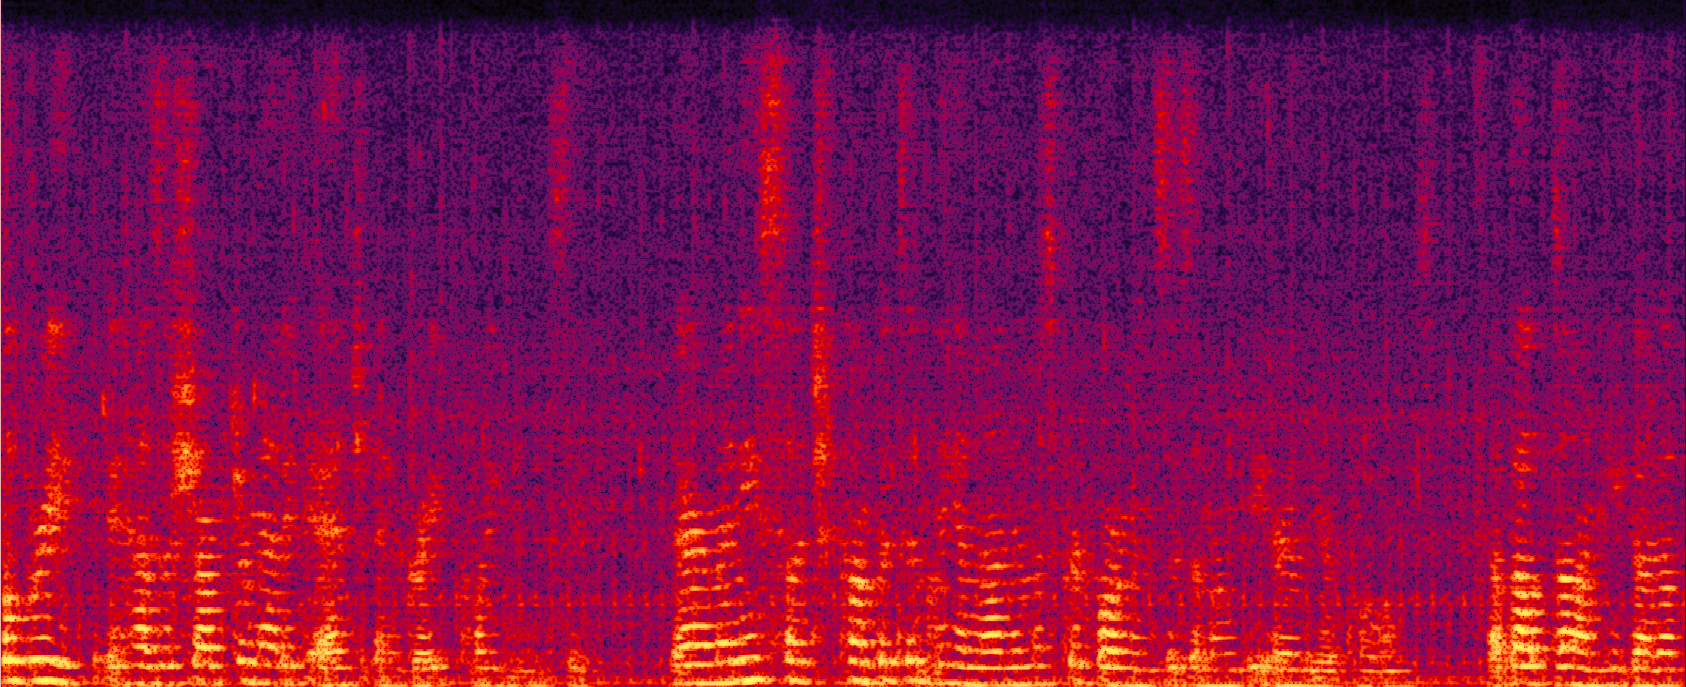
|
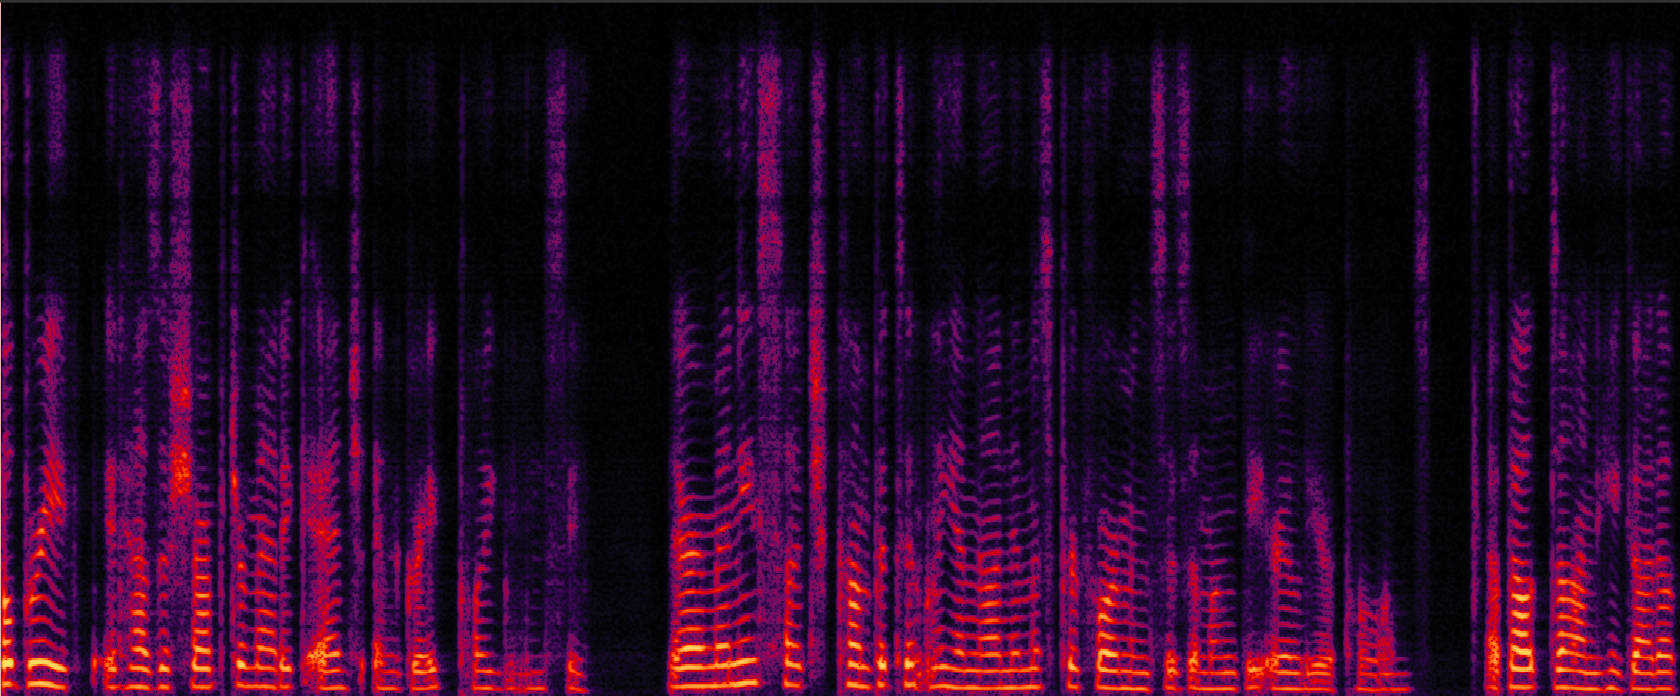
|
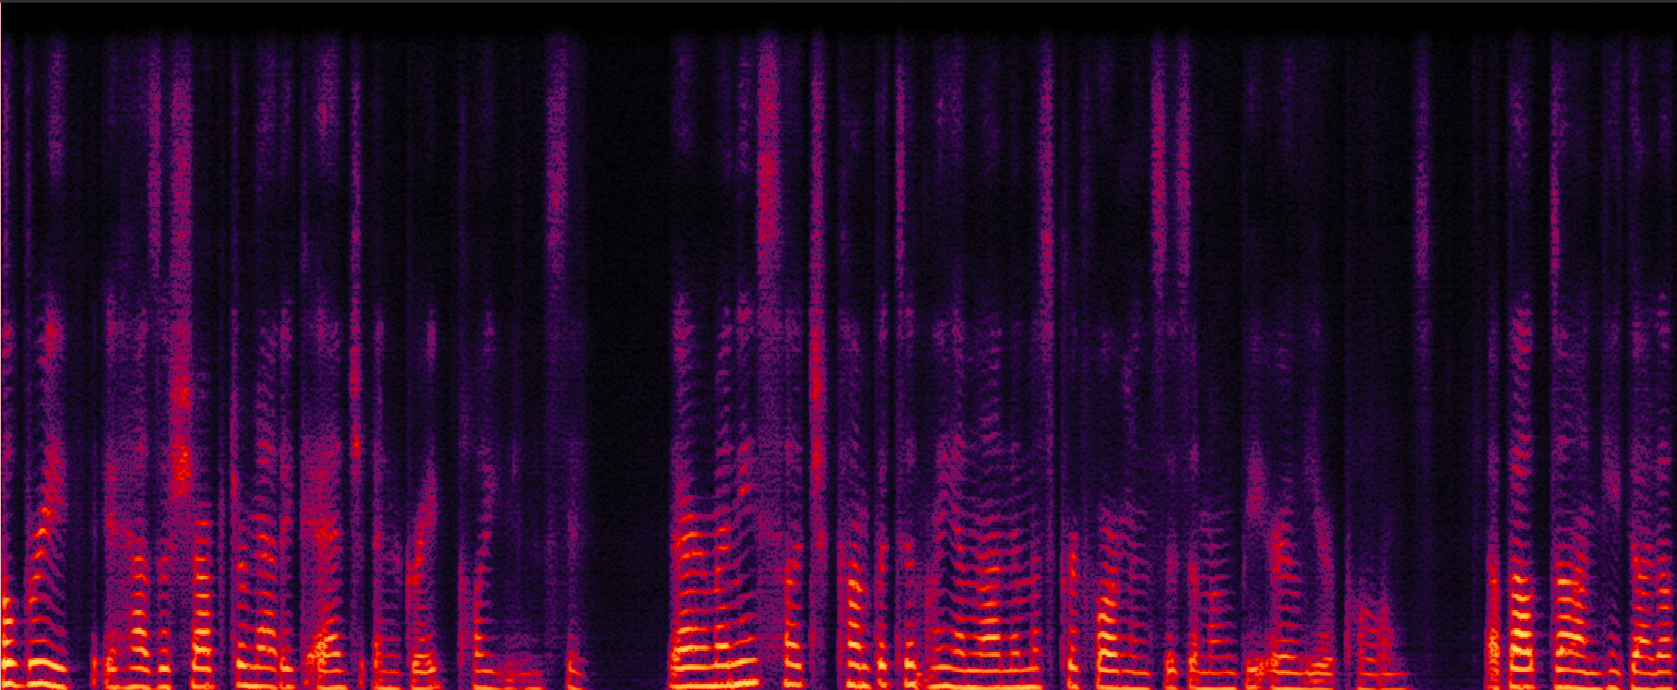
|
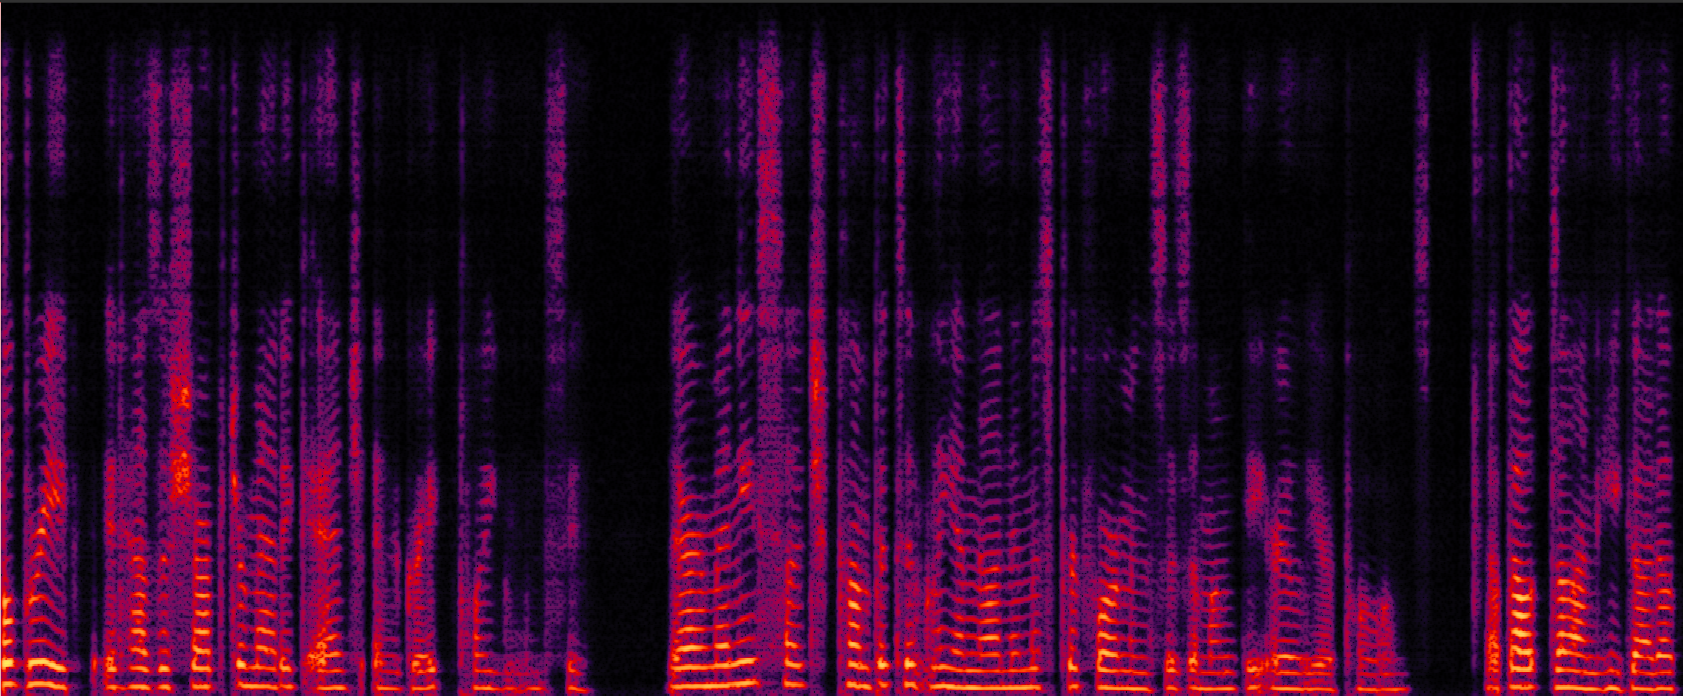
|
Sample 3
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
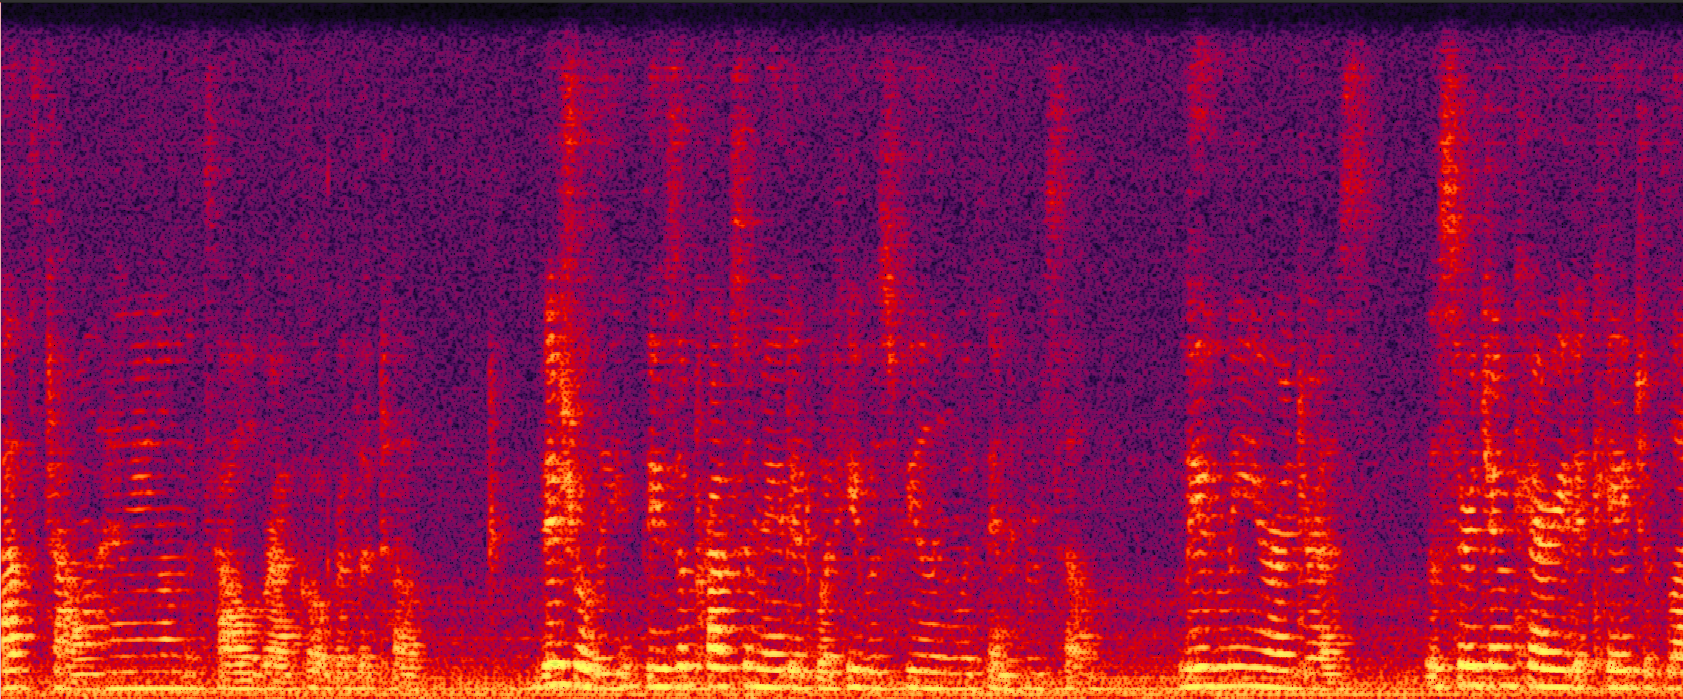
|
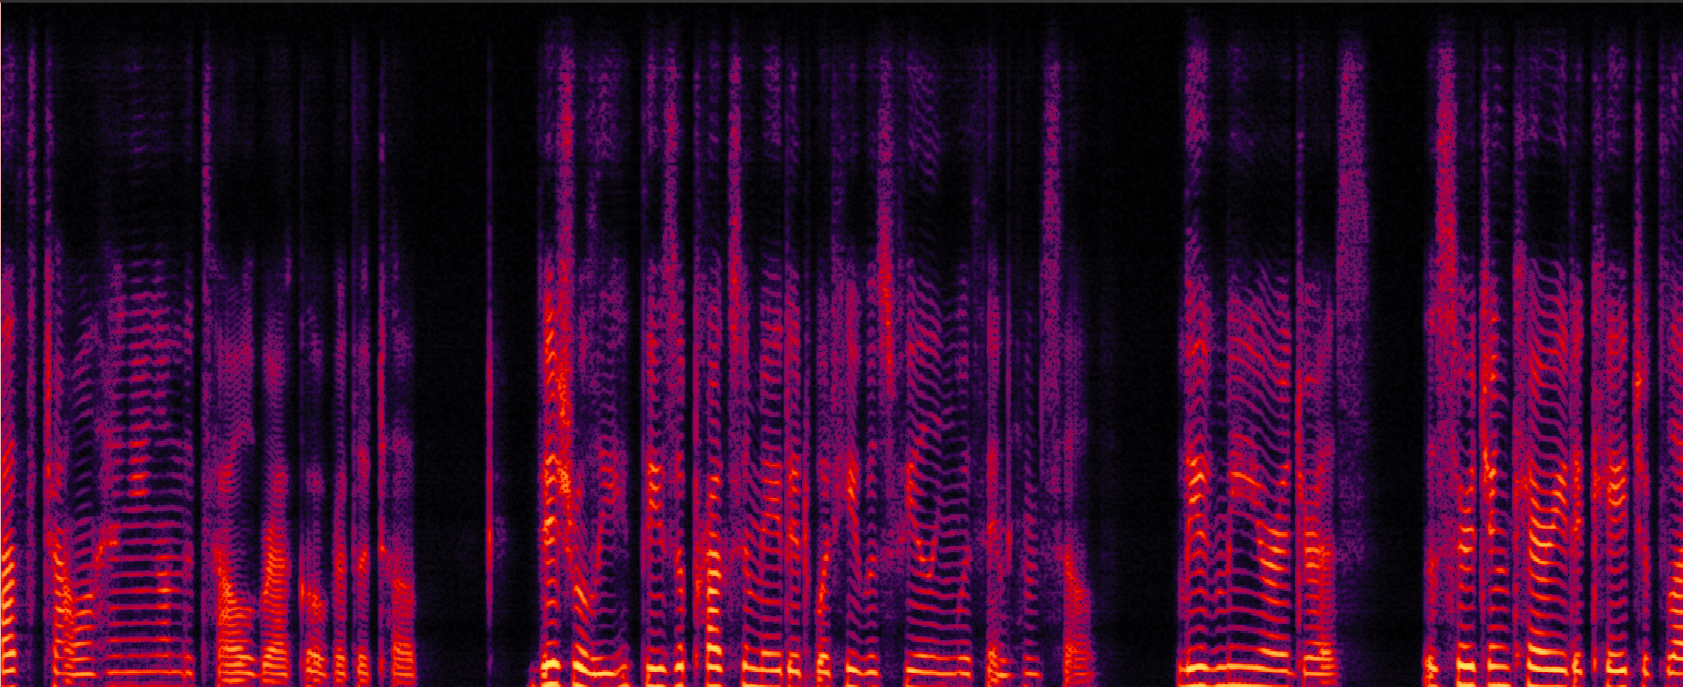
|
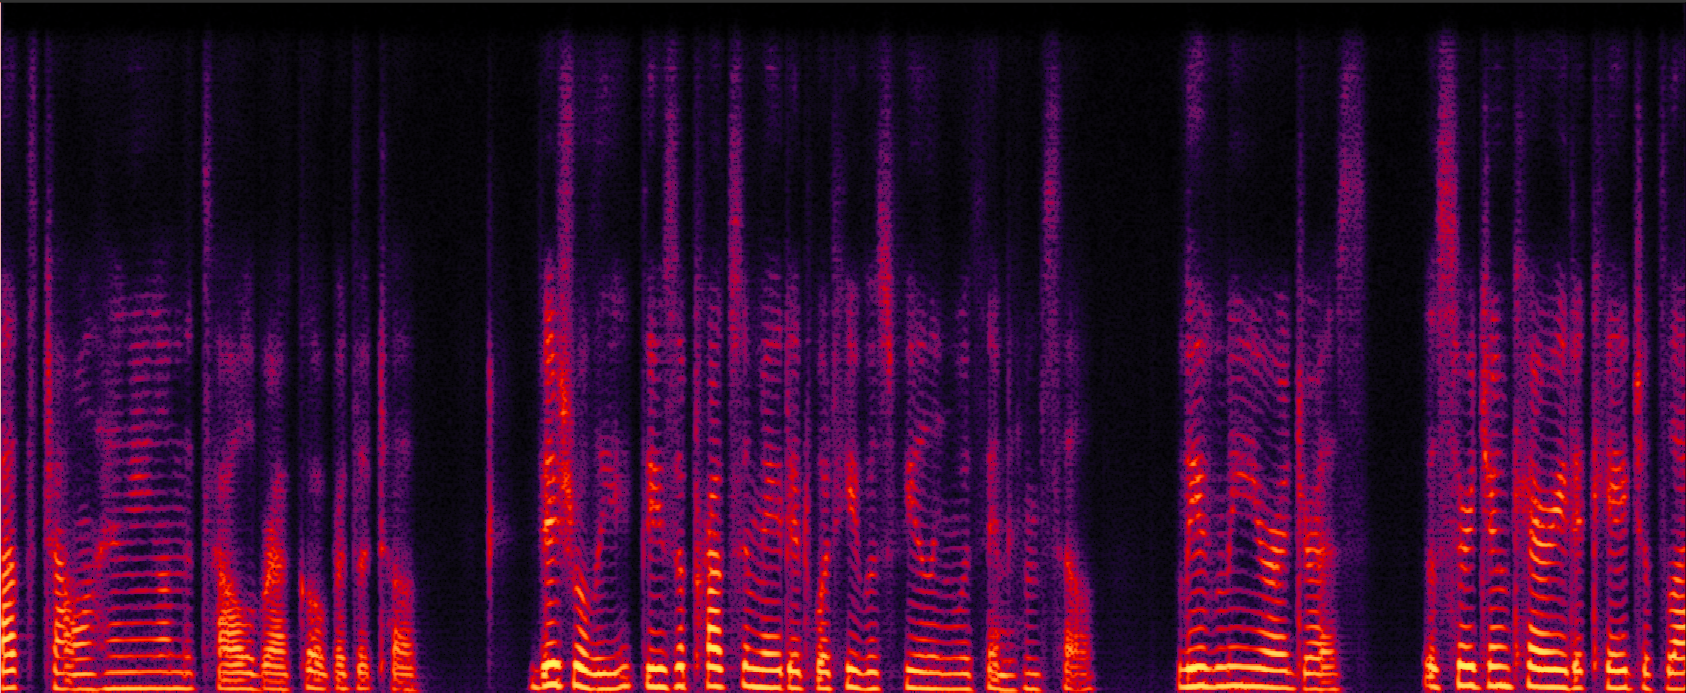
|
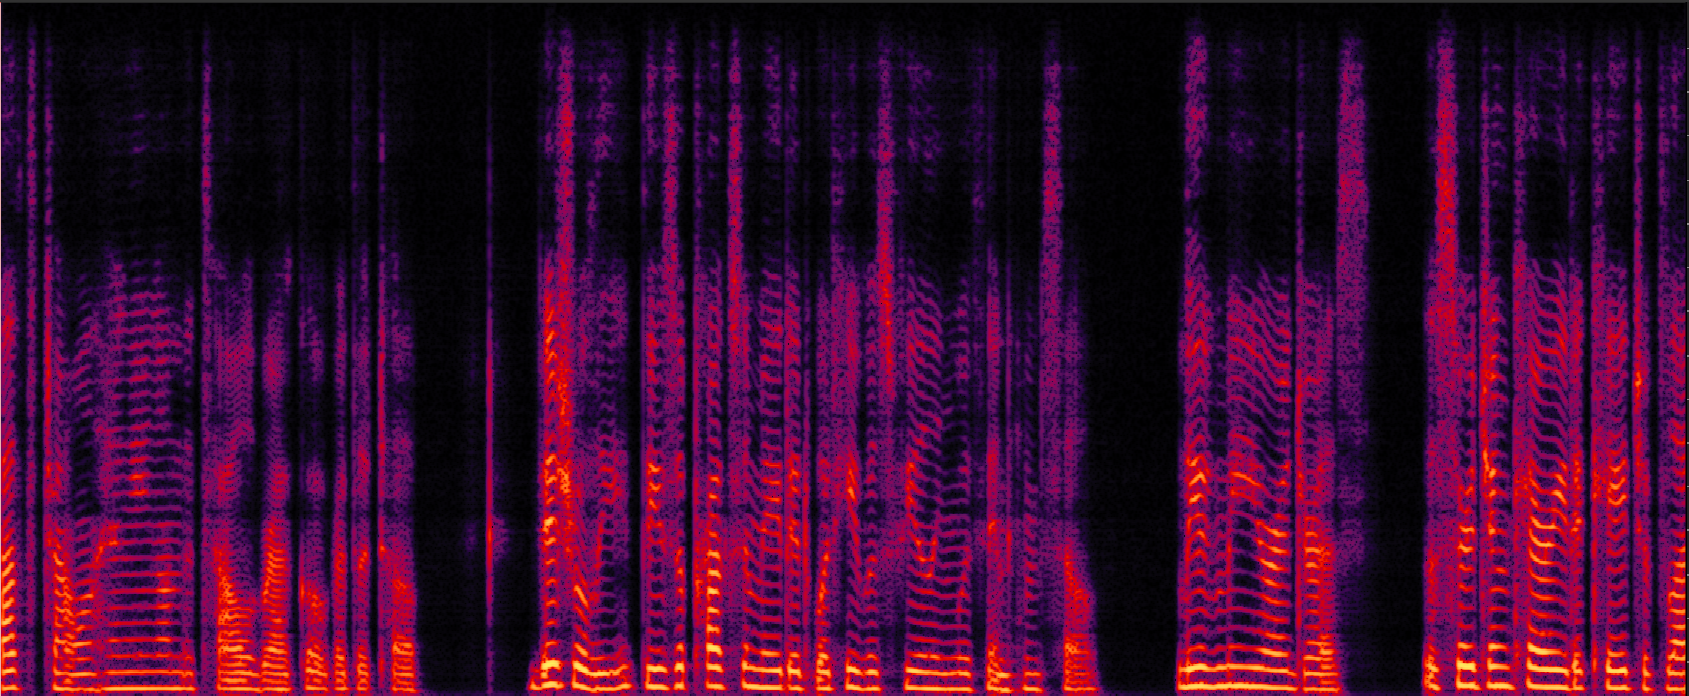
|
DNS Challenge: Real-Recording Test Set
Sample 1
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
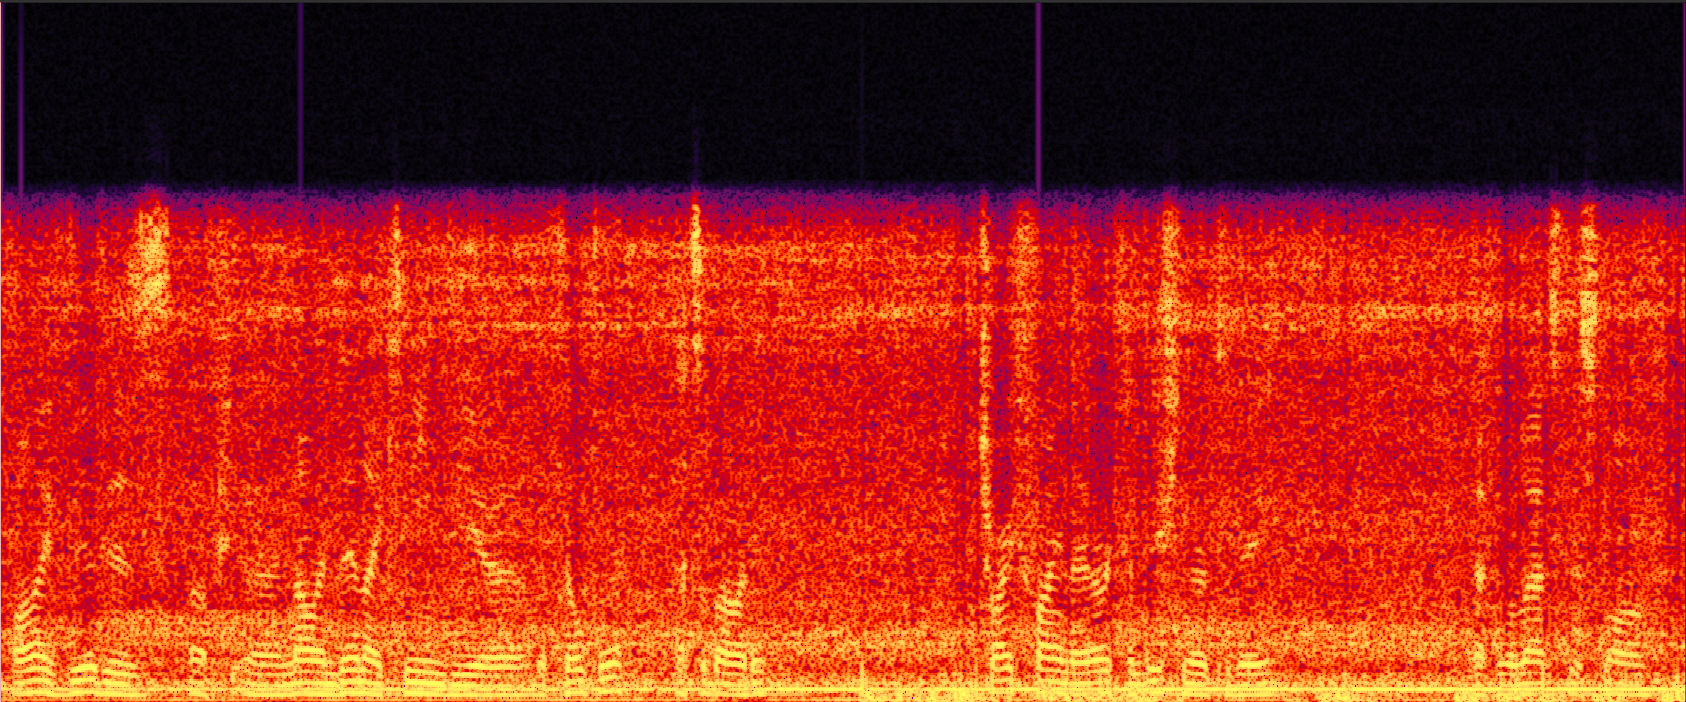
|
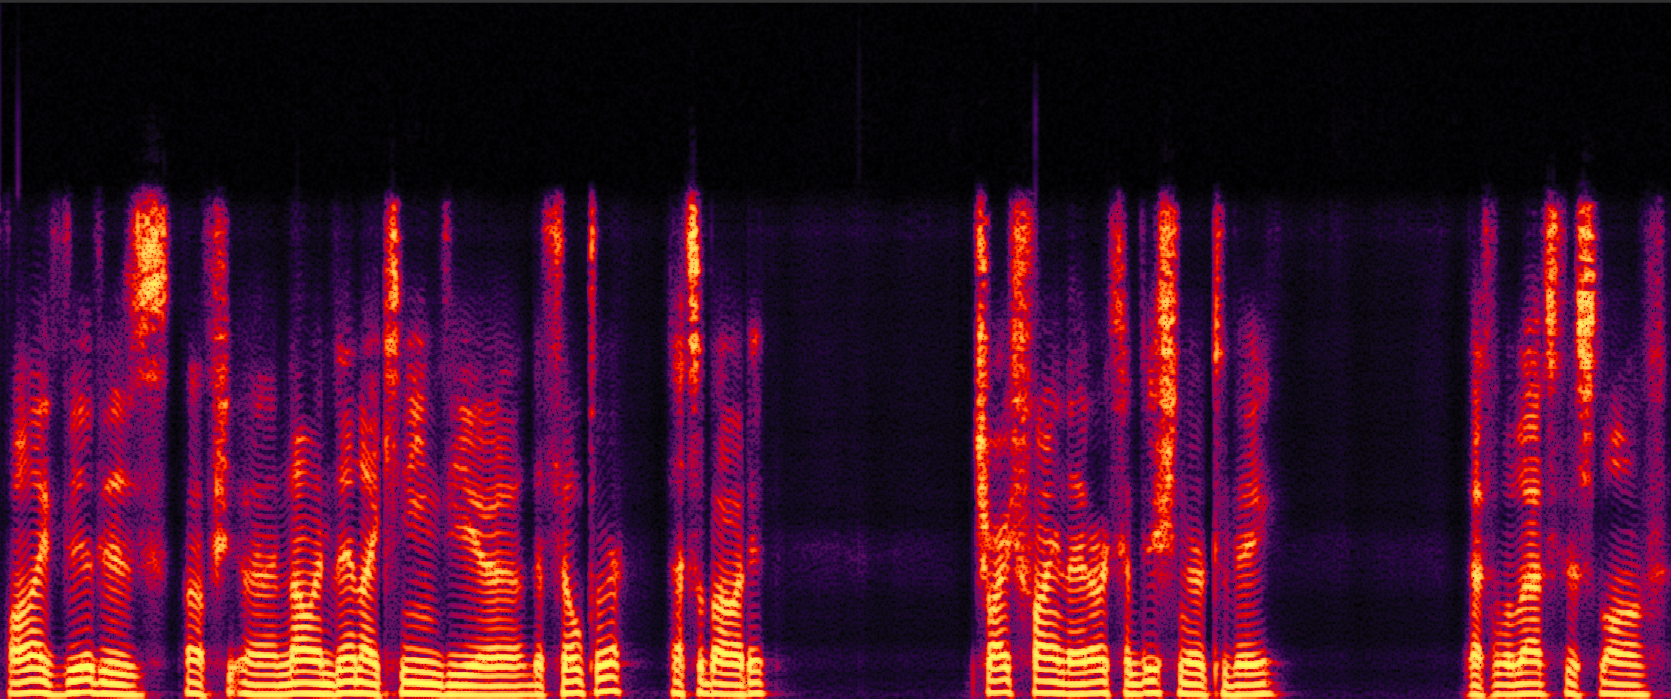
|
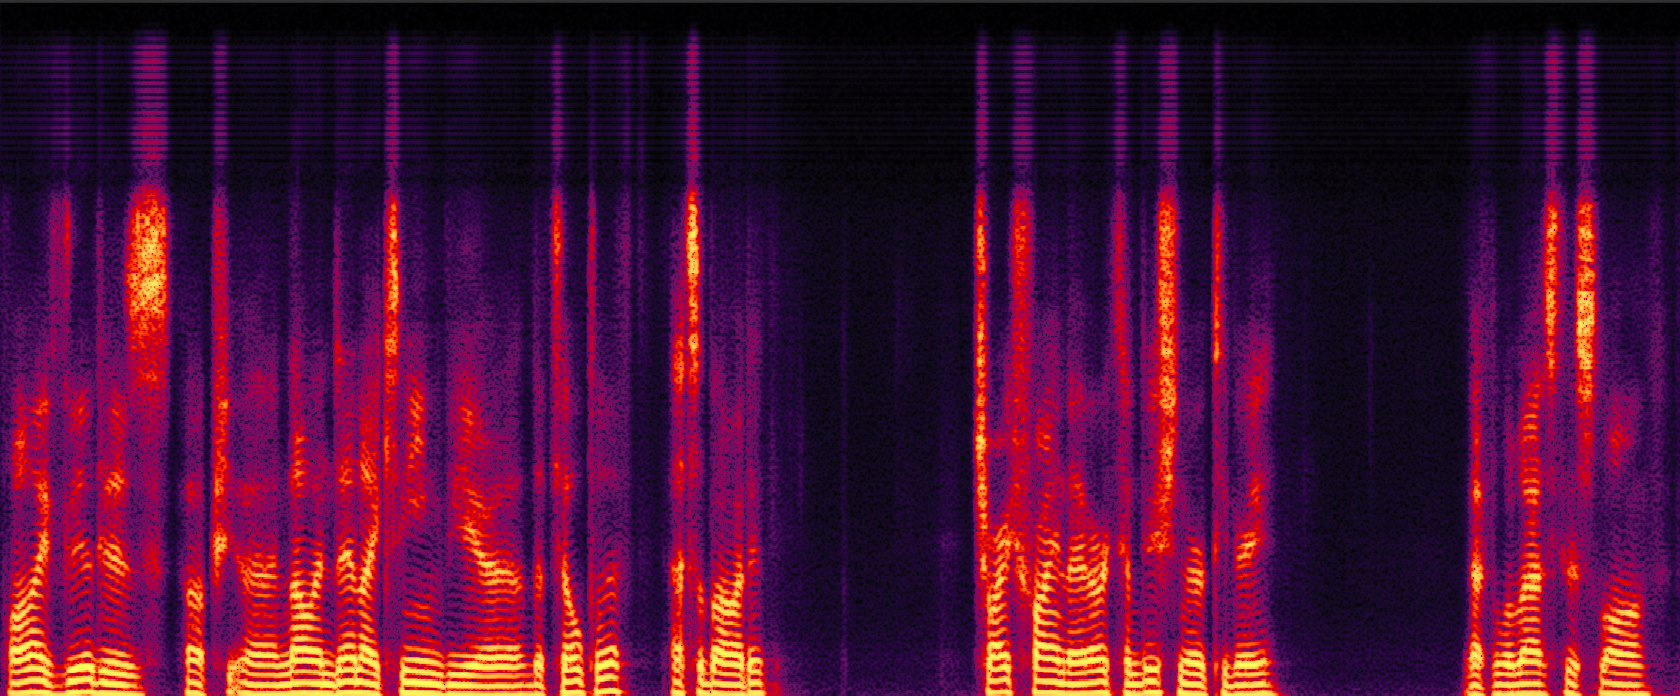
|
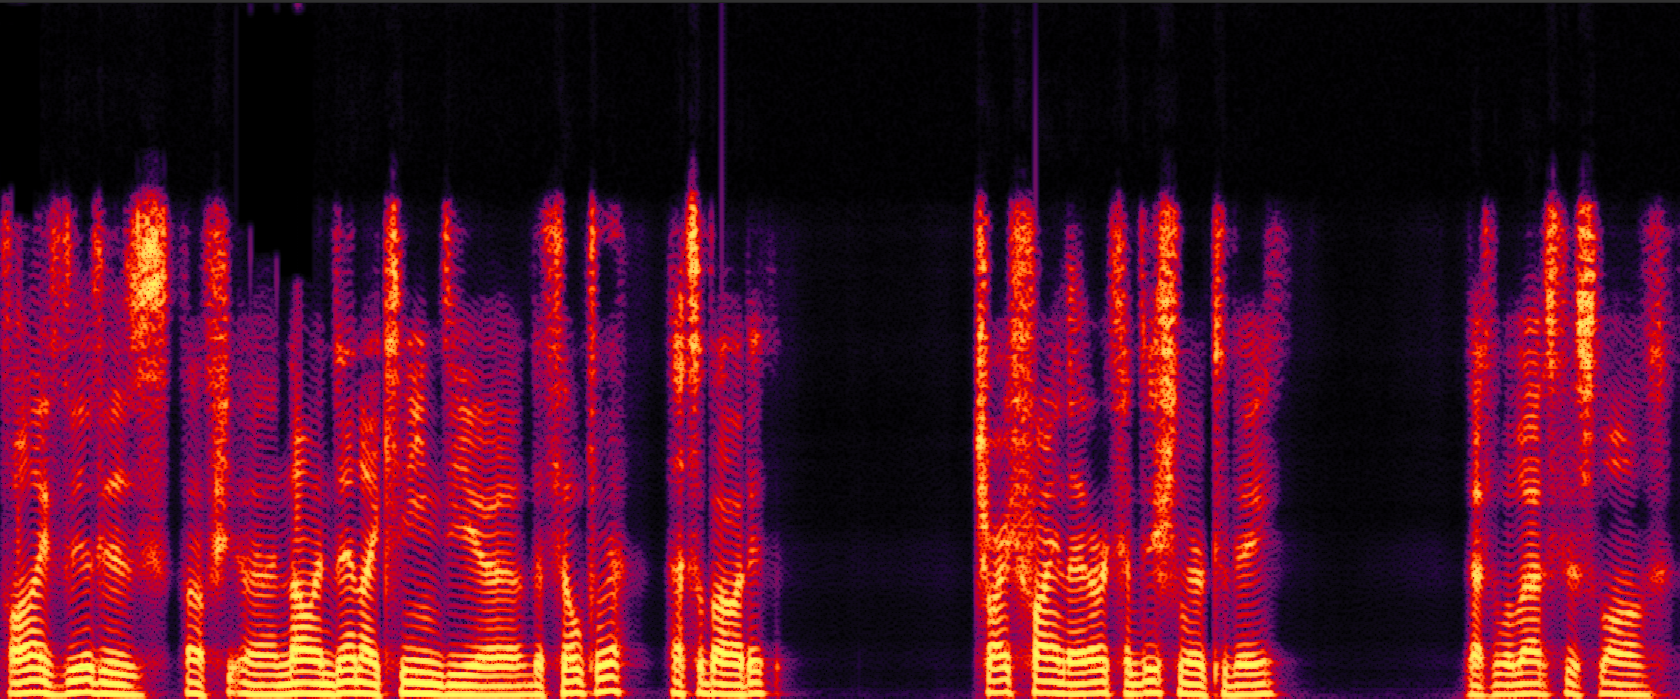
|
Sample 2
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
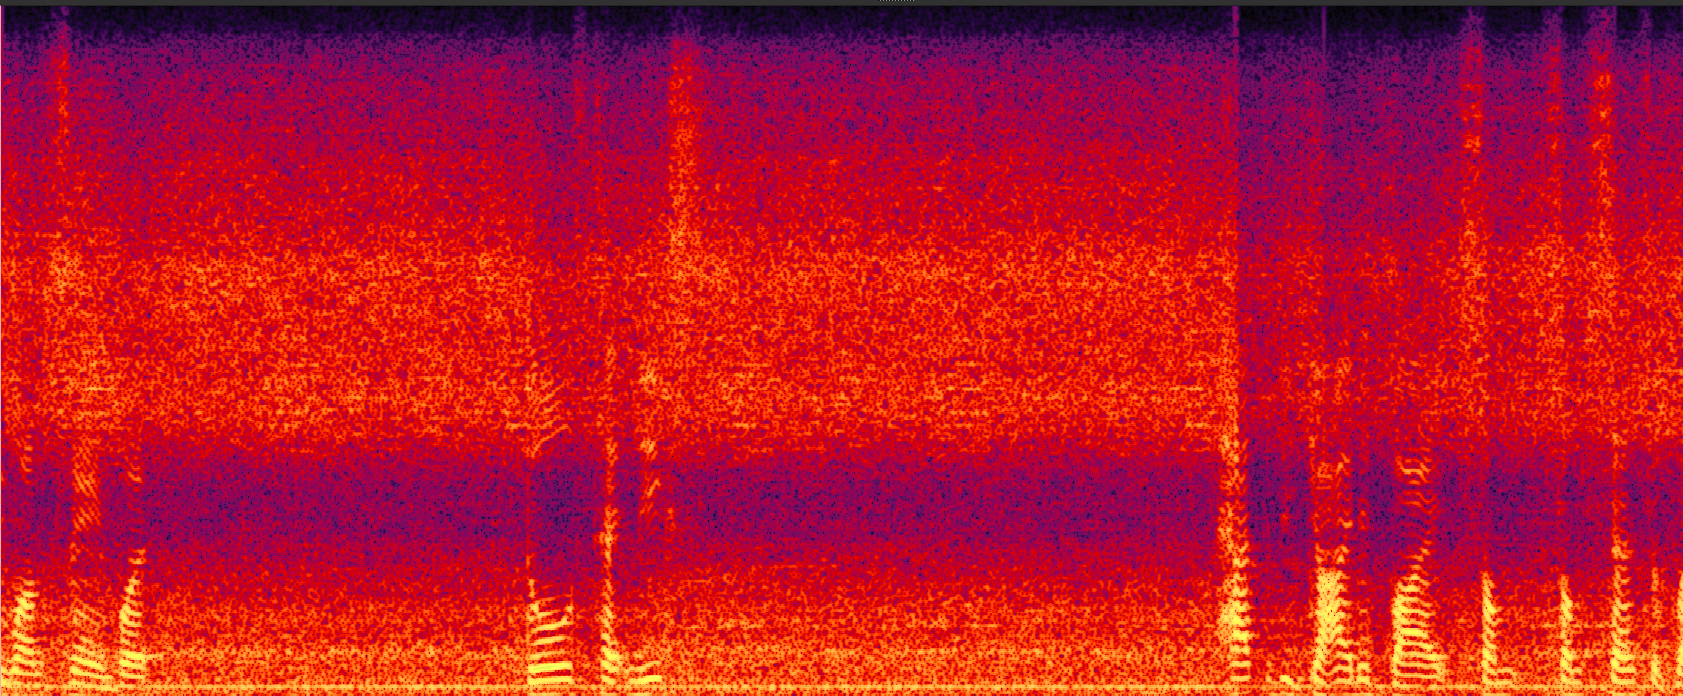
|
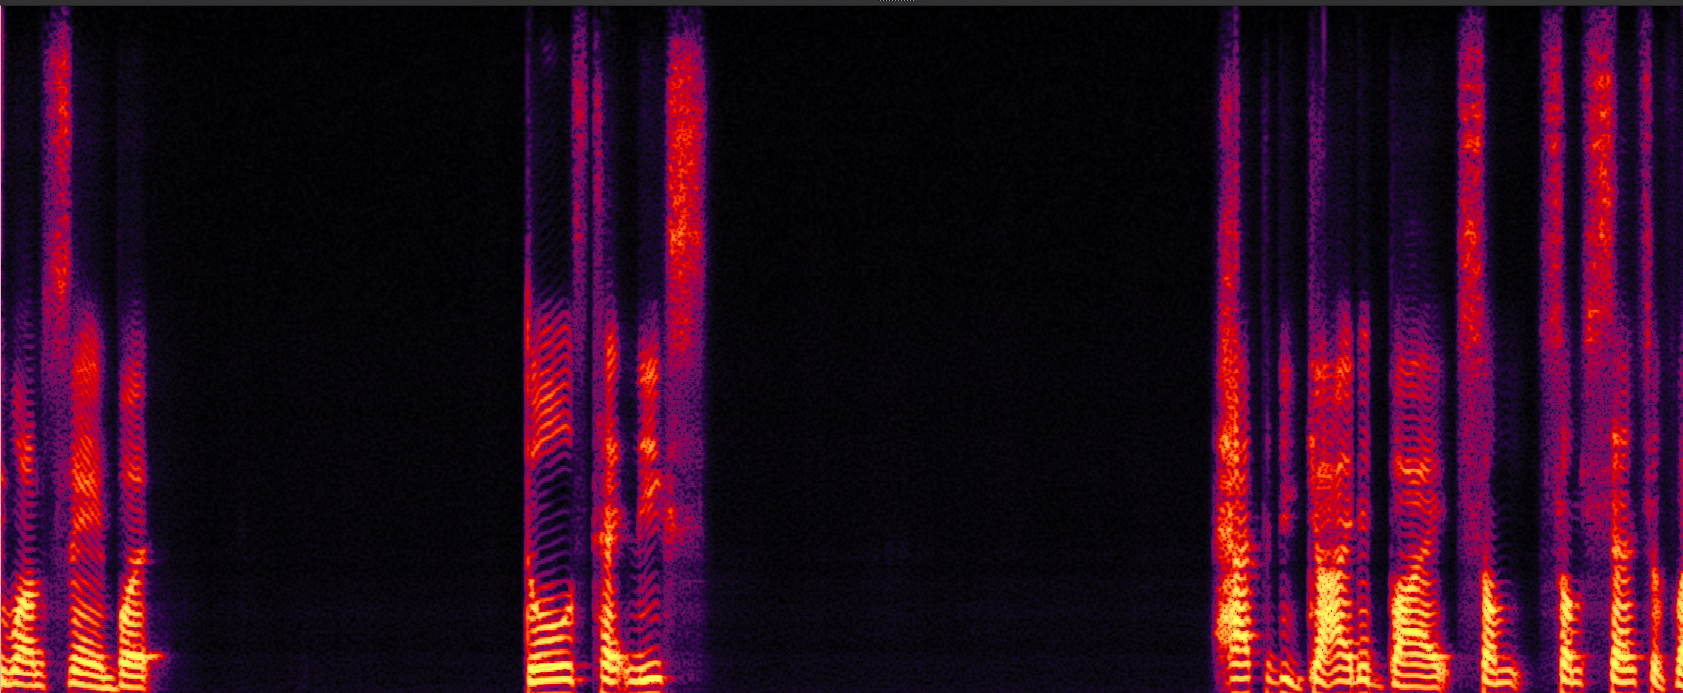
|
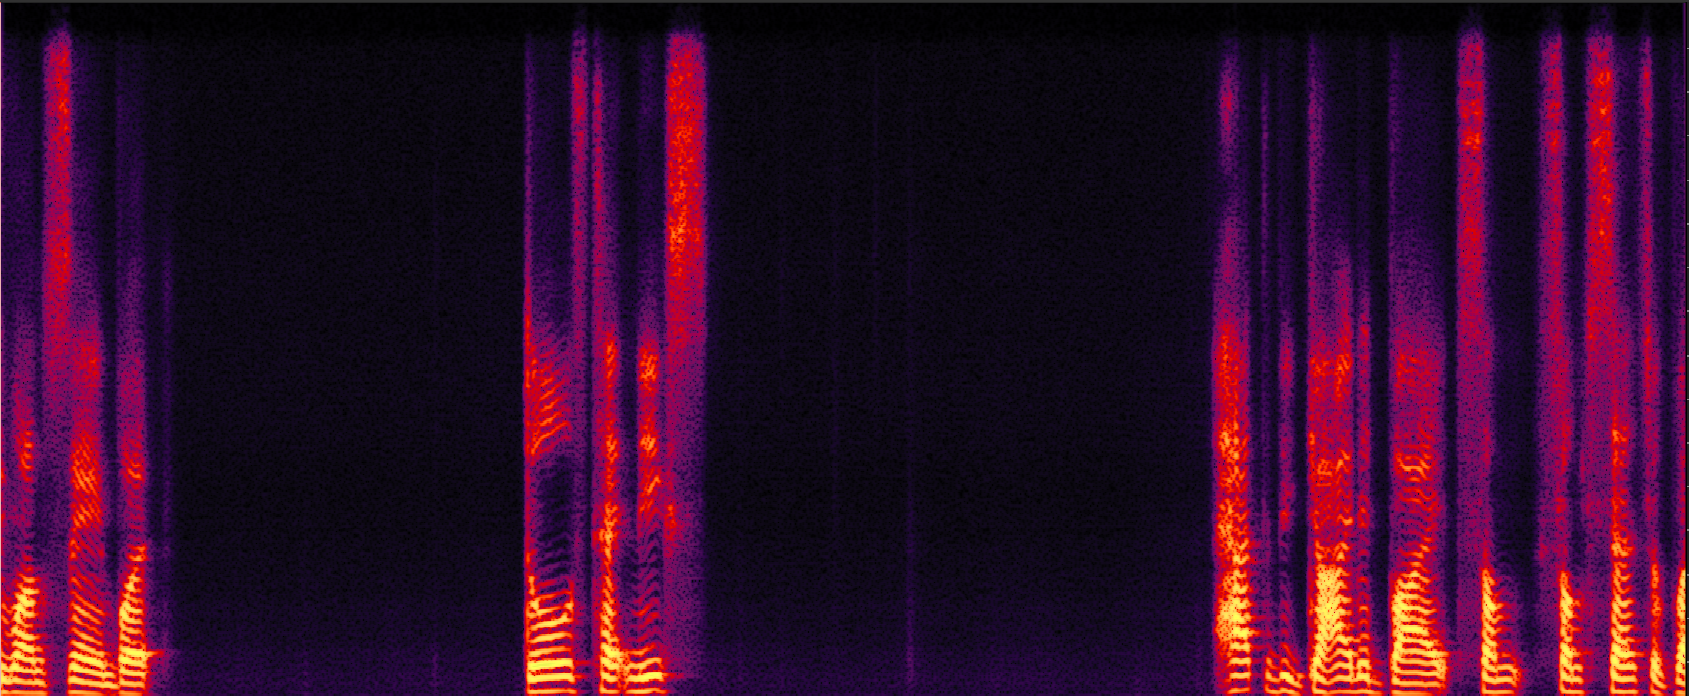
|
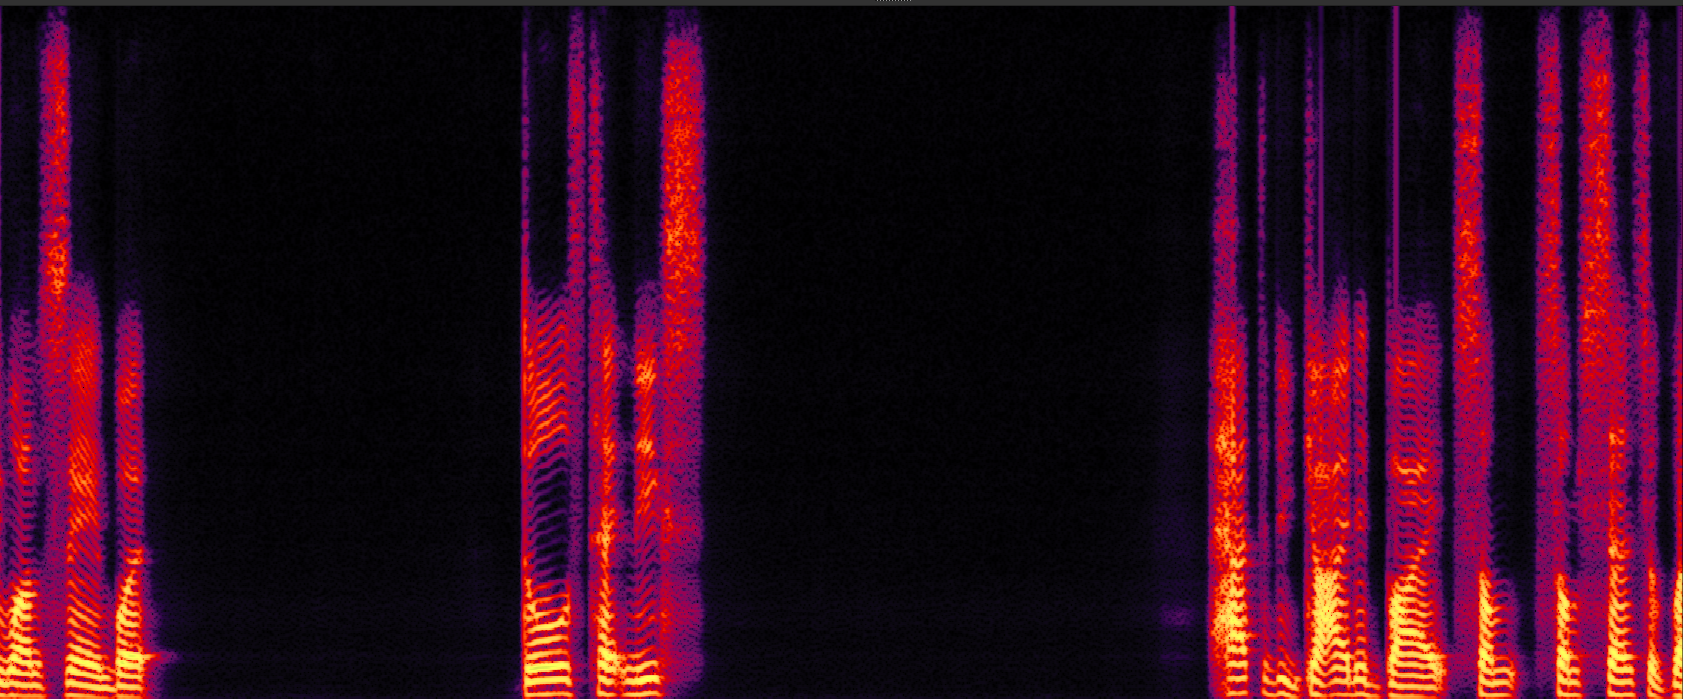
|
Sample 3
| Noisy Speech | SpatialNet | PGUSE | DualSpecSE (Ours) |
|---|---|---|---|
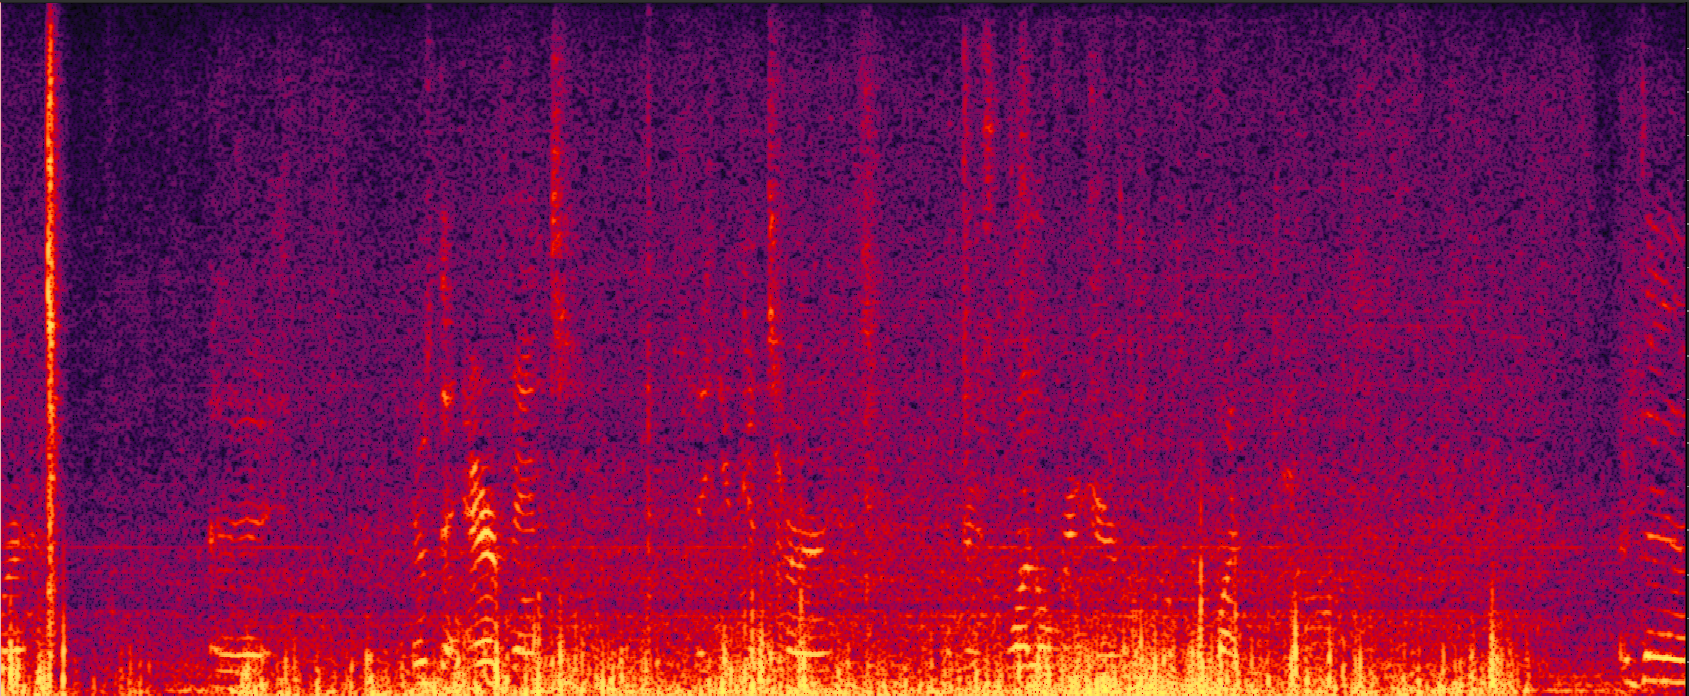
|
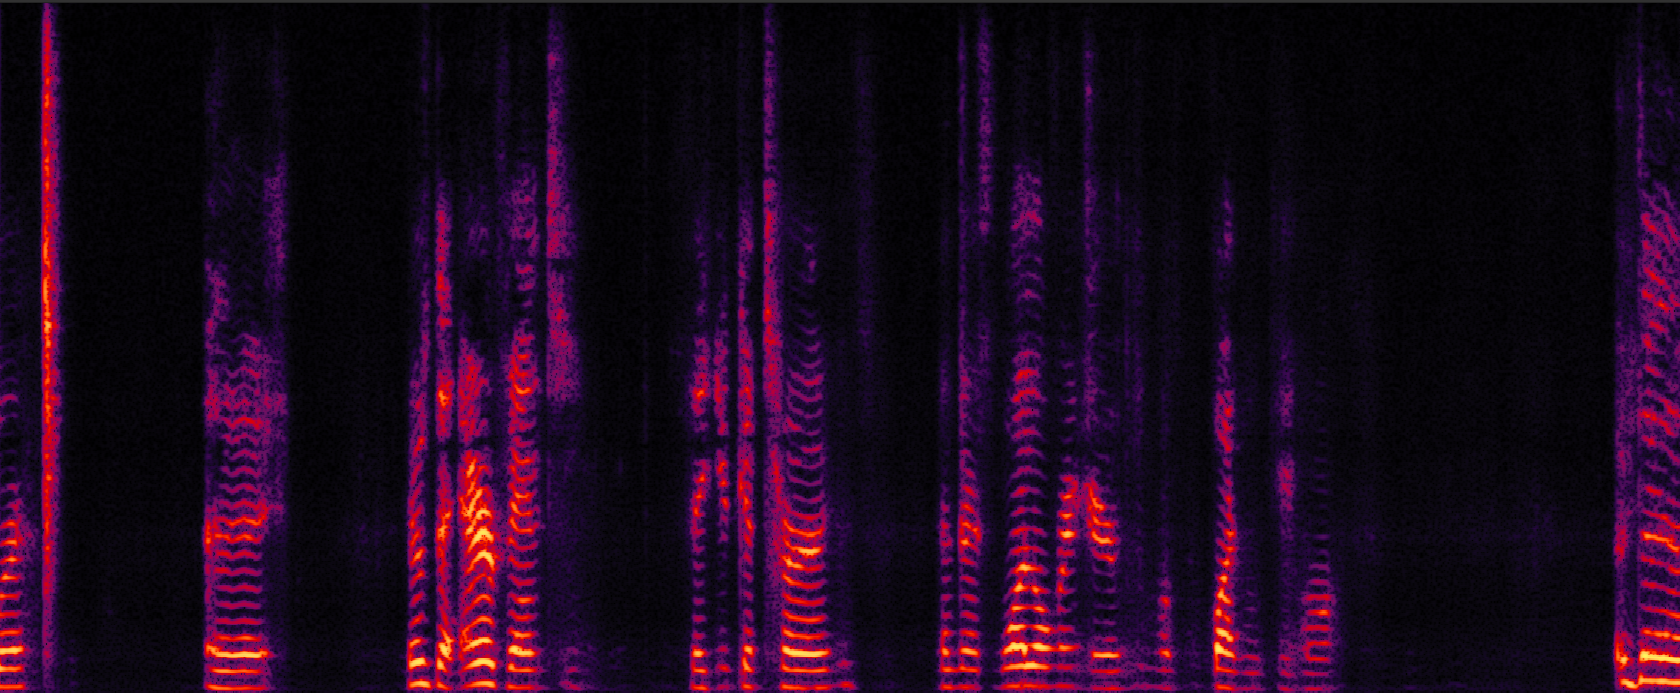
|
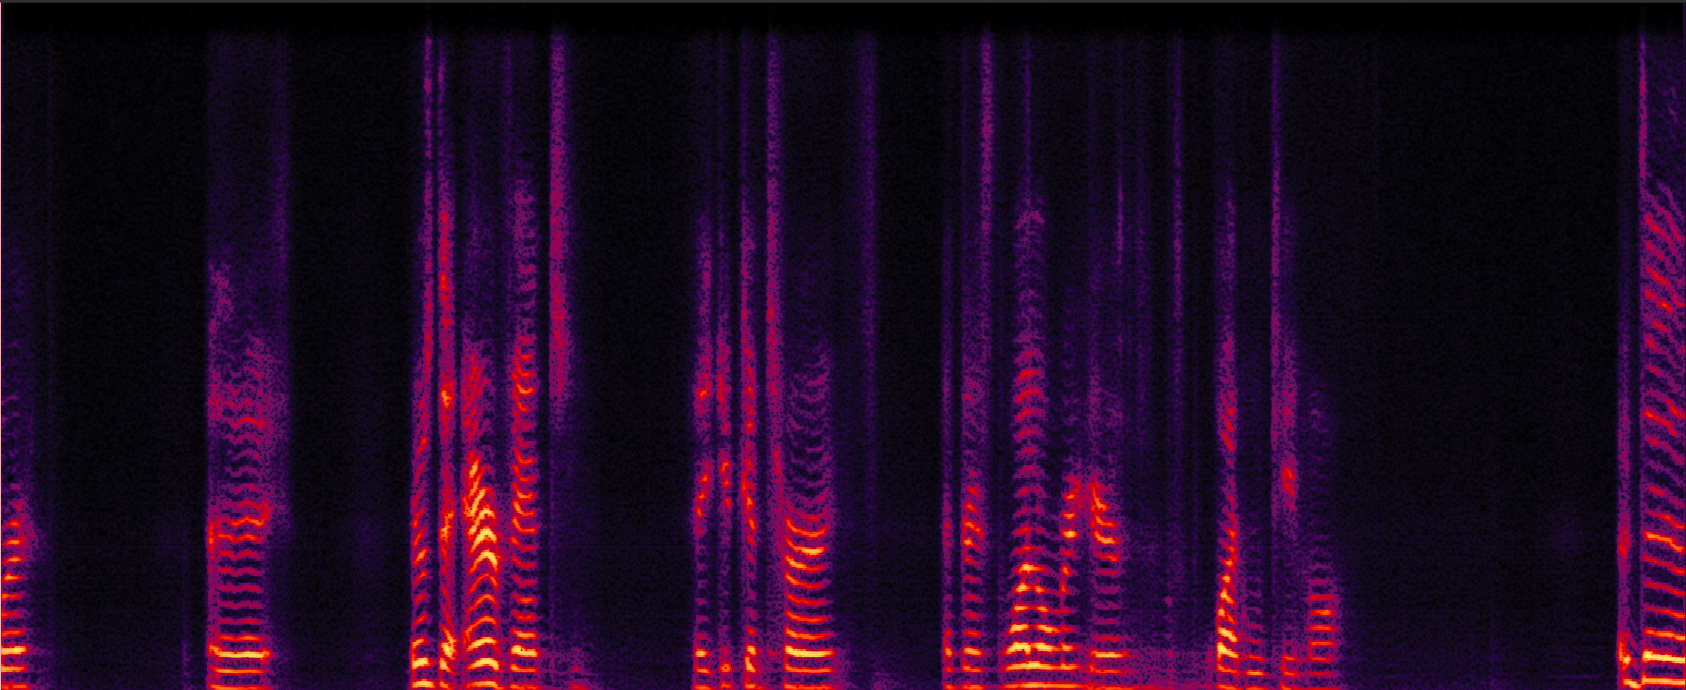
|
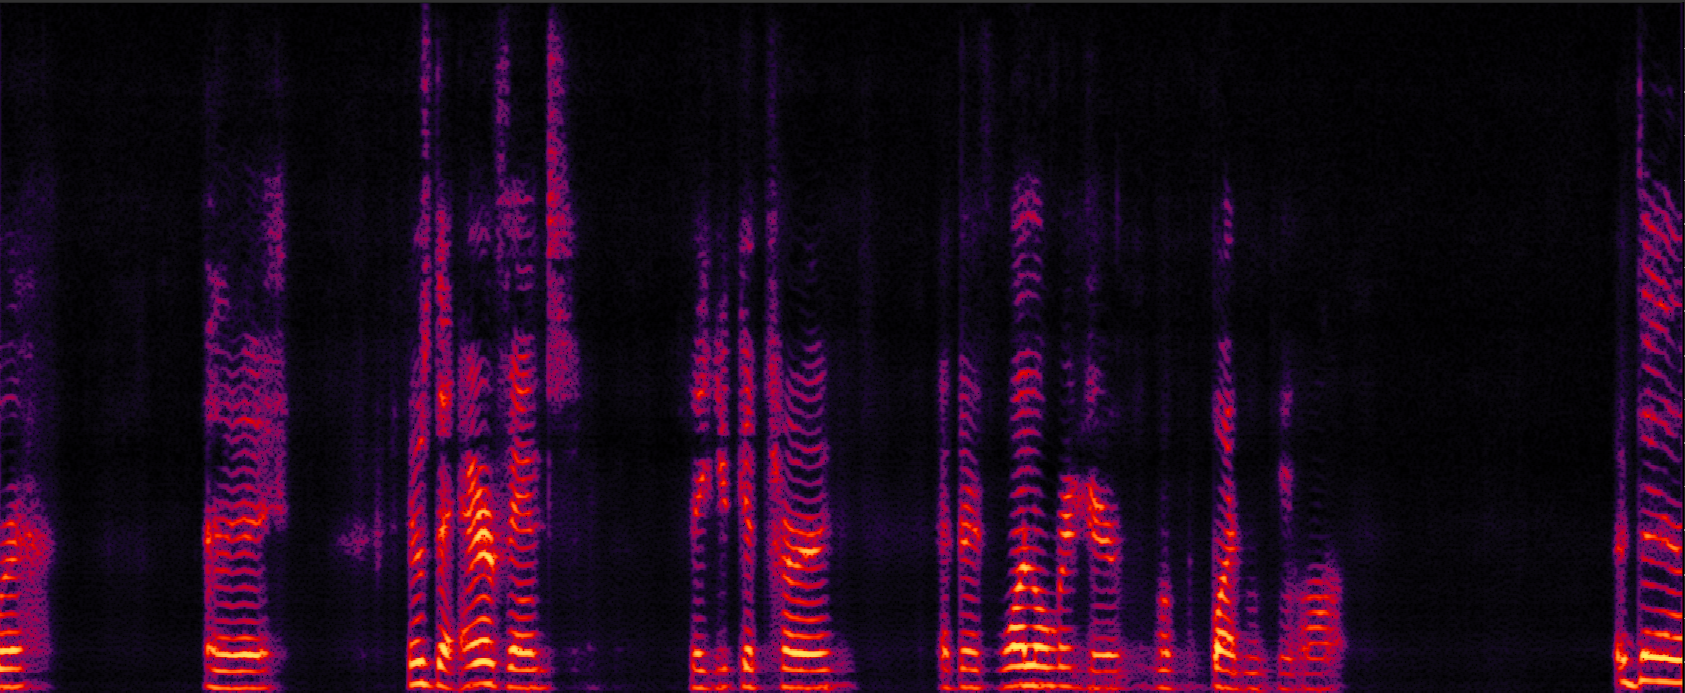
|